GitHub has issues, pull requests and Actions. It has no test case management.
Honest Cheetah puts test cases where the requirements are, runs them with a record of who did what against which build, and keeps that record after the sprint is over. Teams coming from Azure DevOps notice the gap on day one. Teams that started on GitHub have been keeping test cases in a spreadsheet, a wiki page or nowhere, and calling the PR checks "testing."
Test management is part of the paid plan. Any member of your organization can try it for 15 days, five people, no credit card.
Test cases live with the requirement
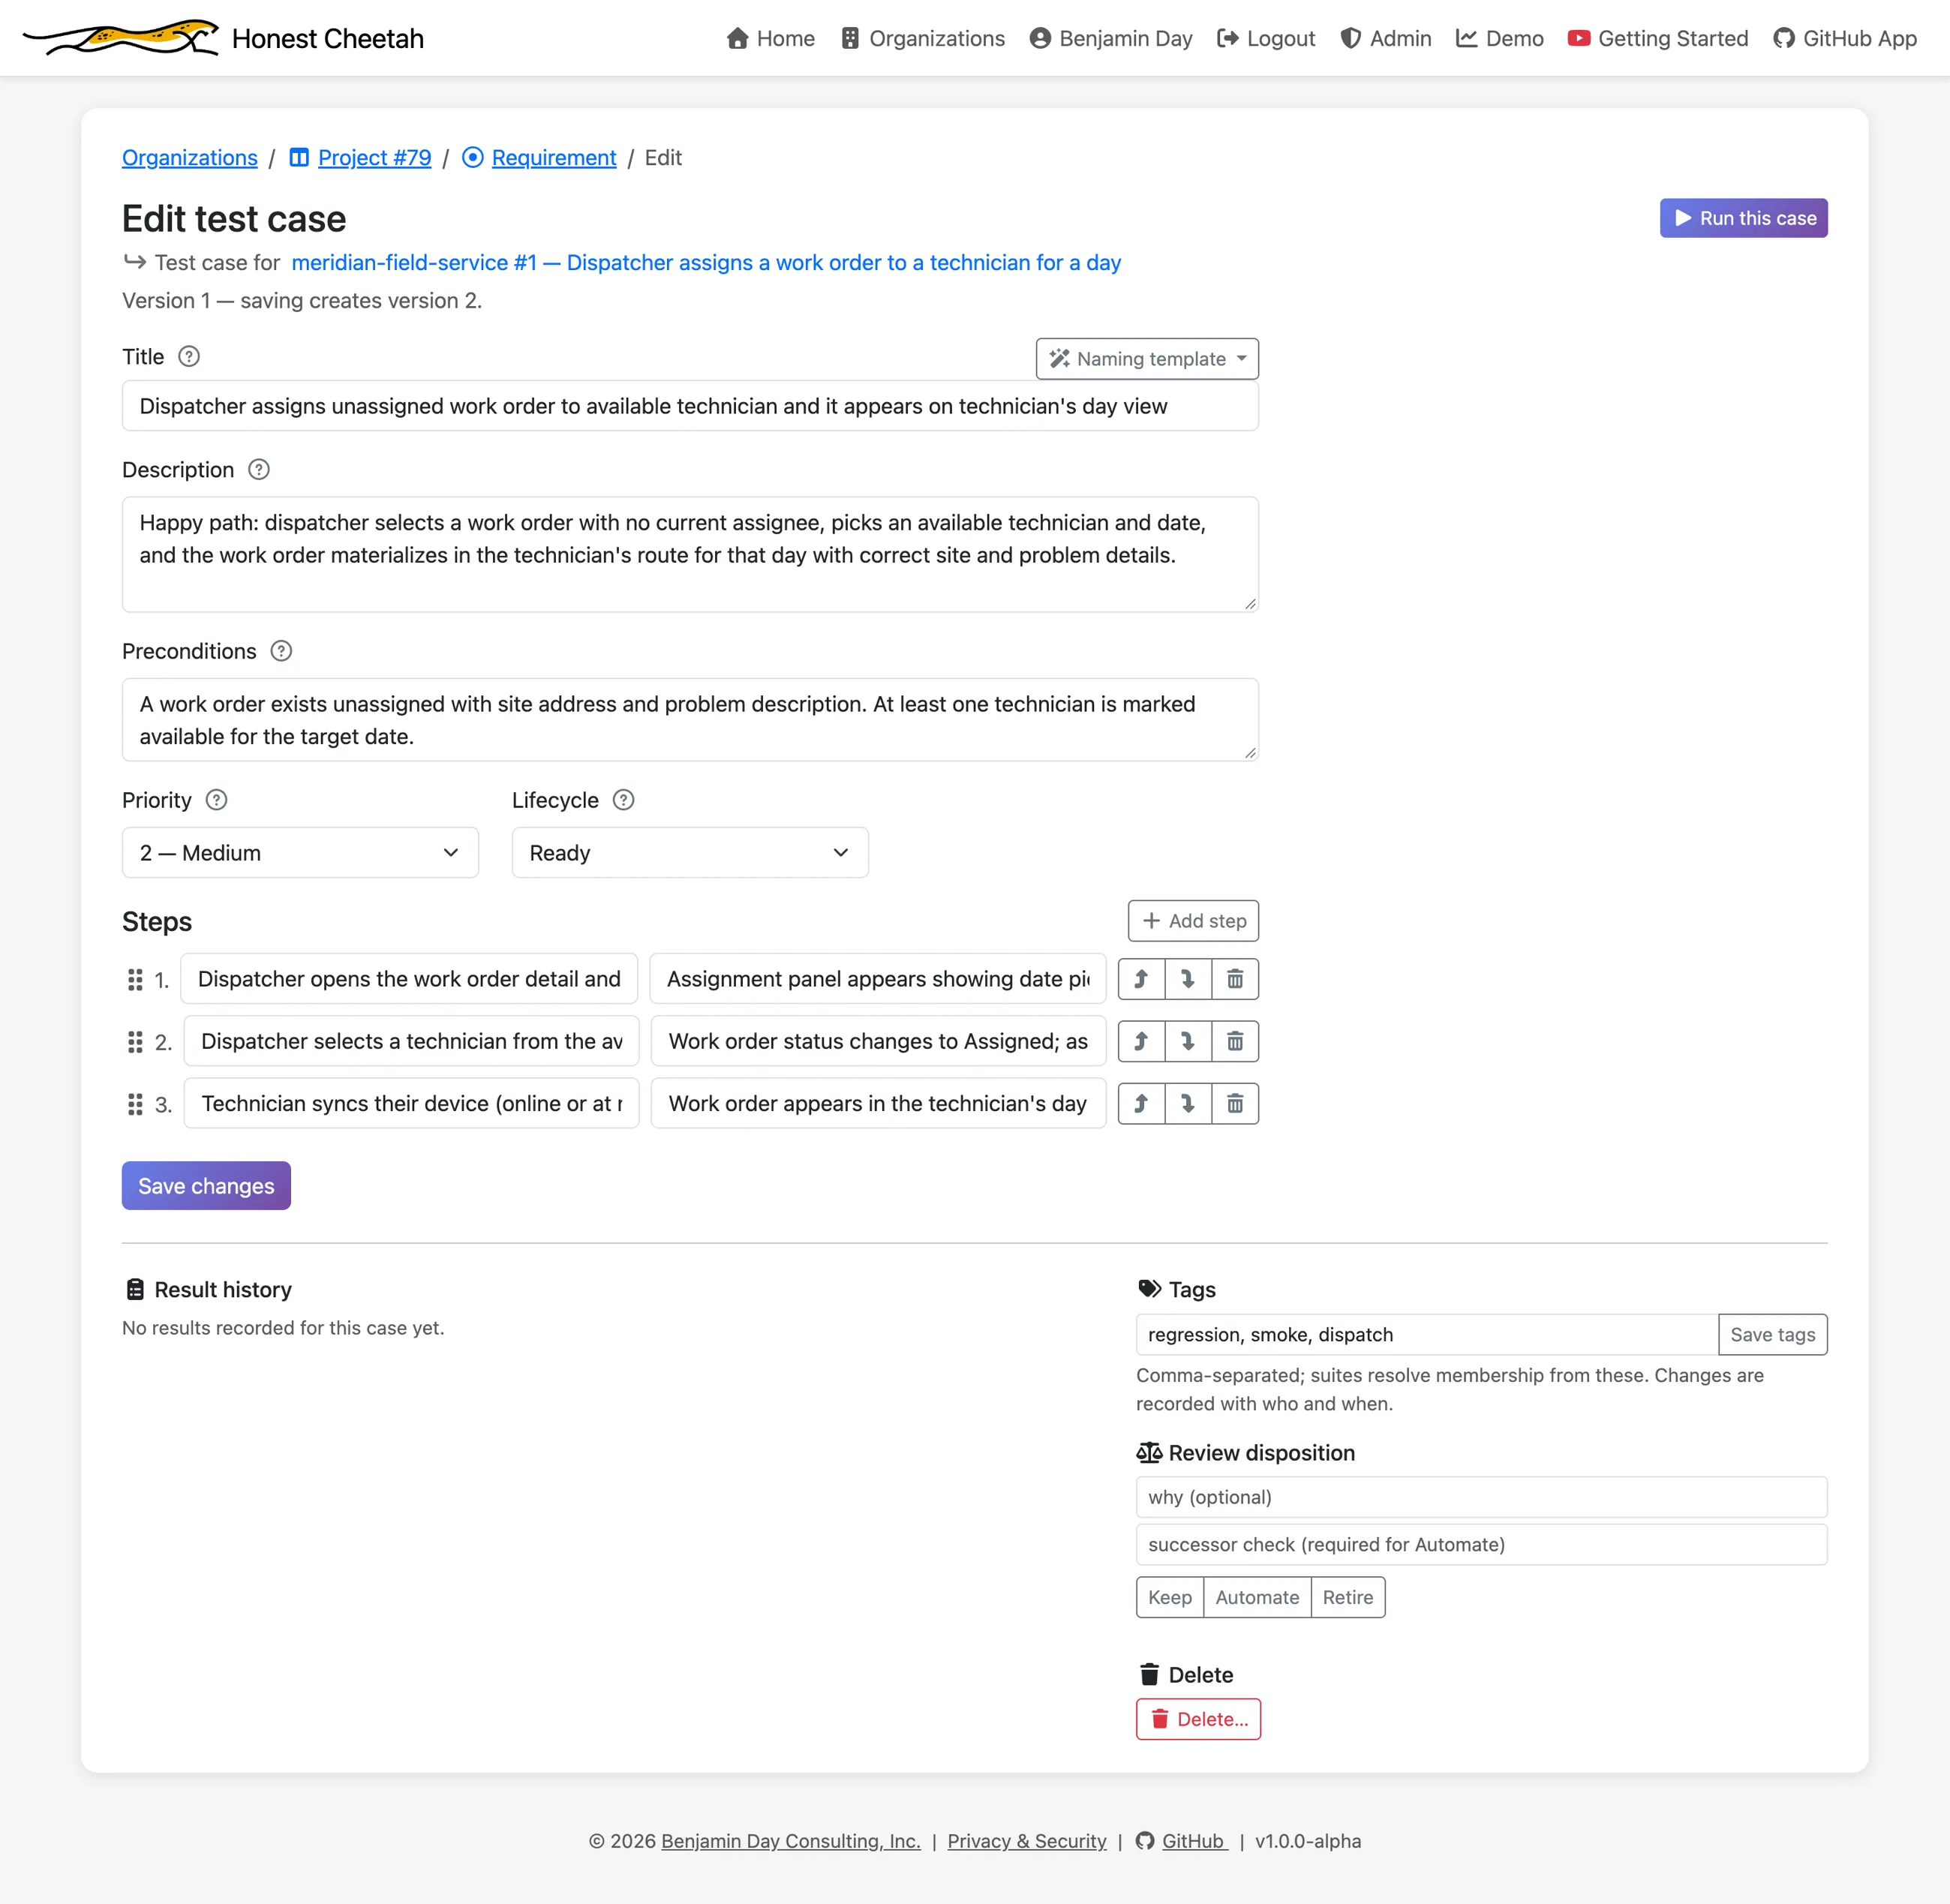
A test case belongs to a requirement: a real GitHub issue on your Projects board. Open the requirement and its cases are listed under it. That link is the whole point: when someone asks "was this story tested?" the answer is on the story.
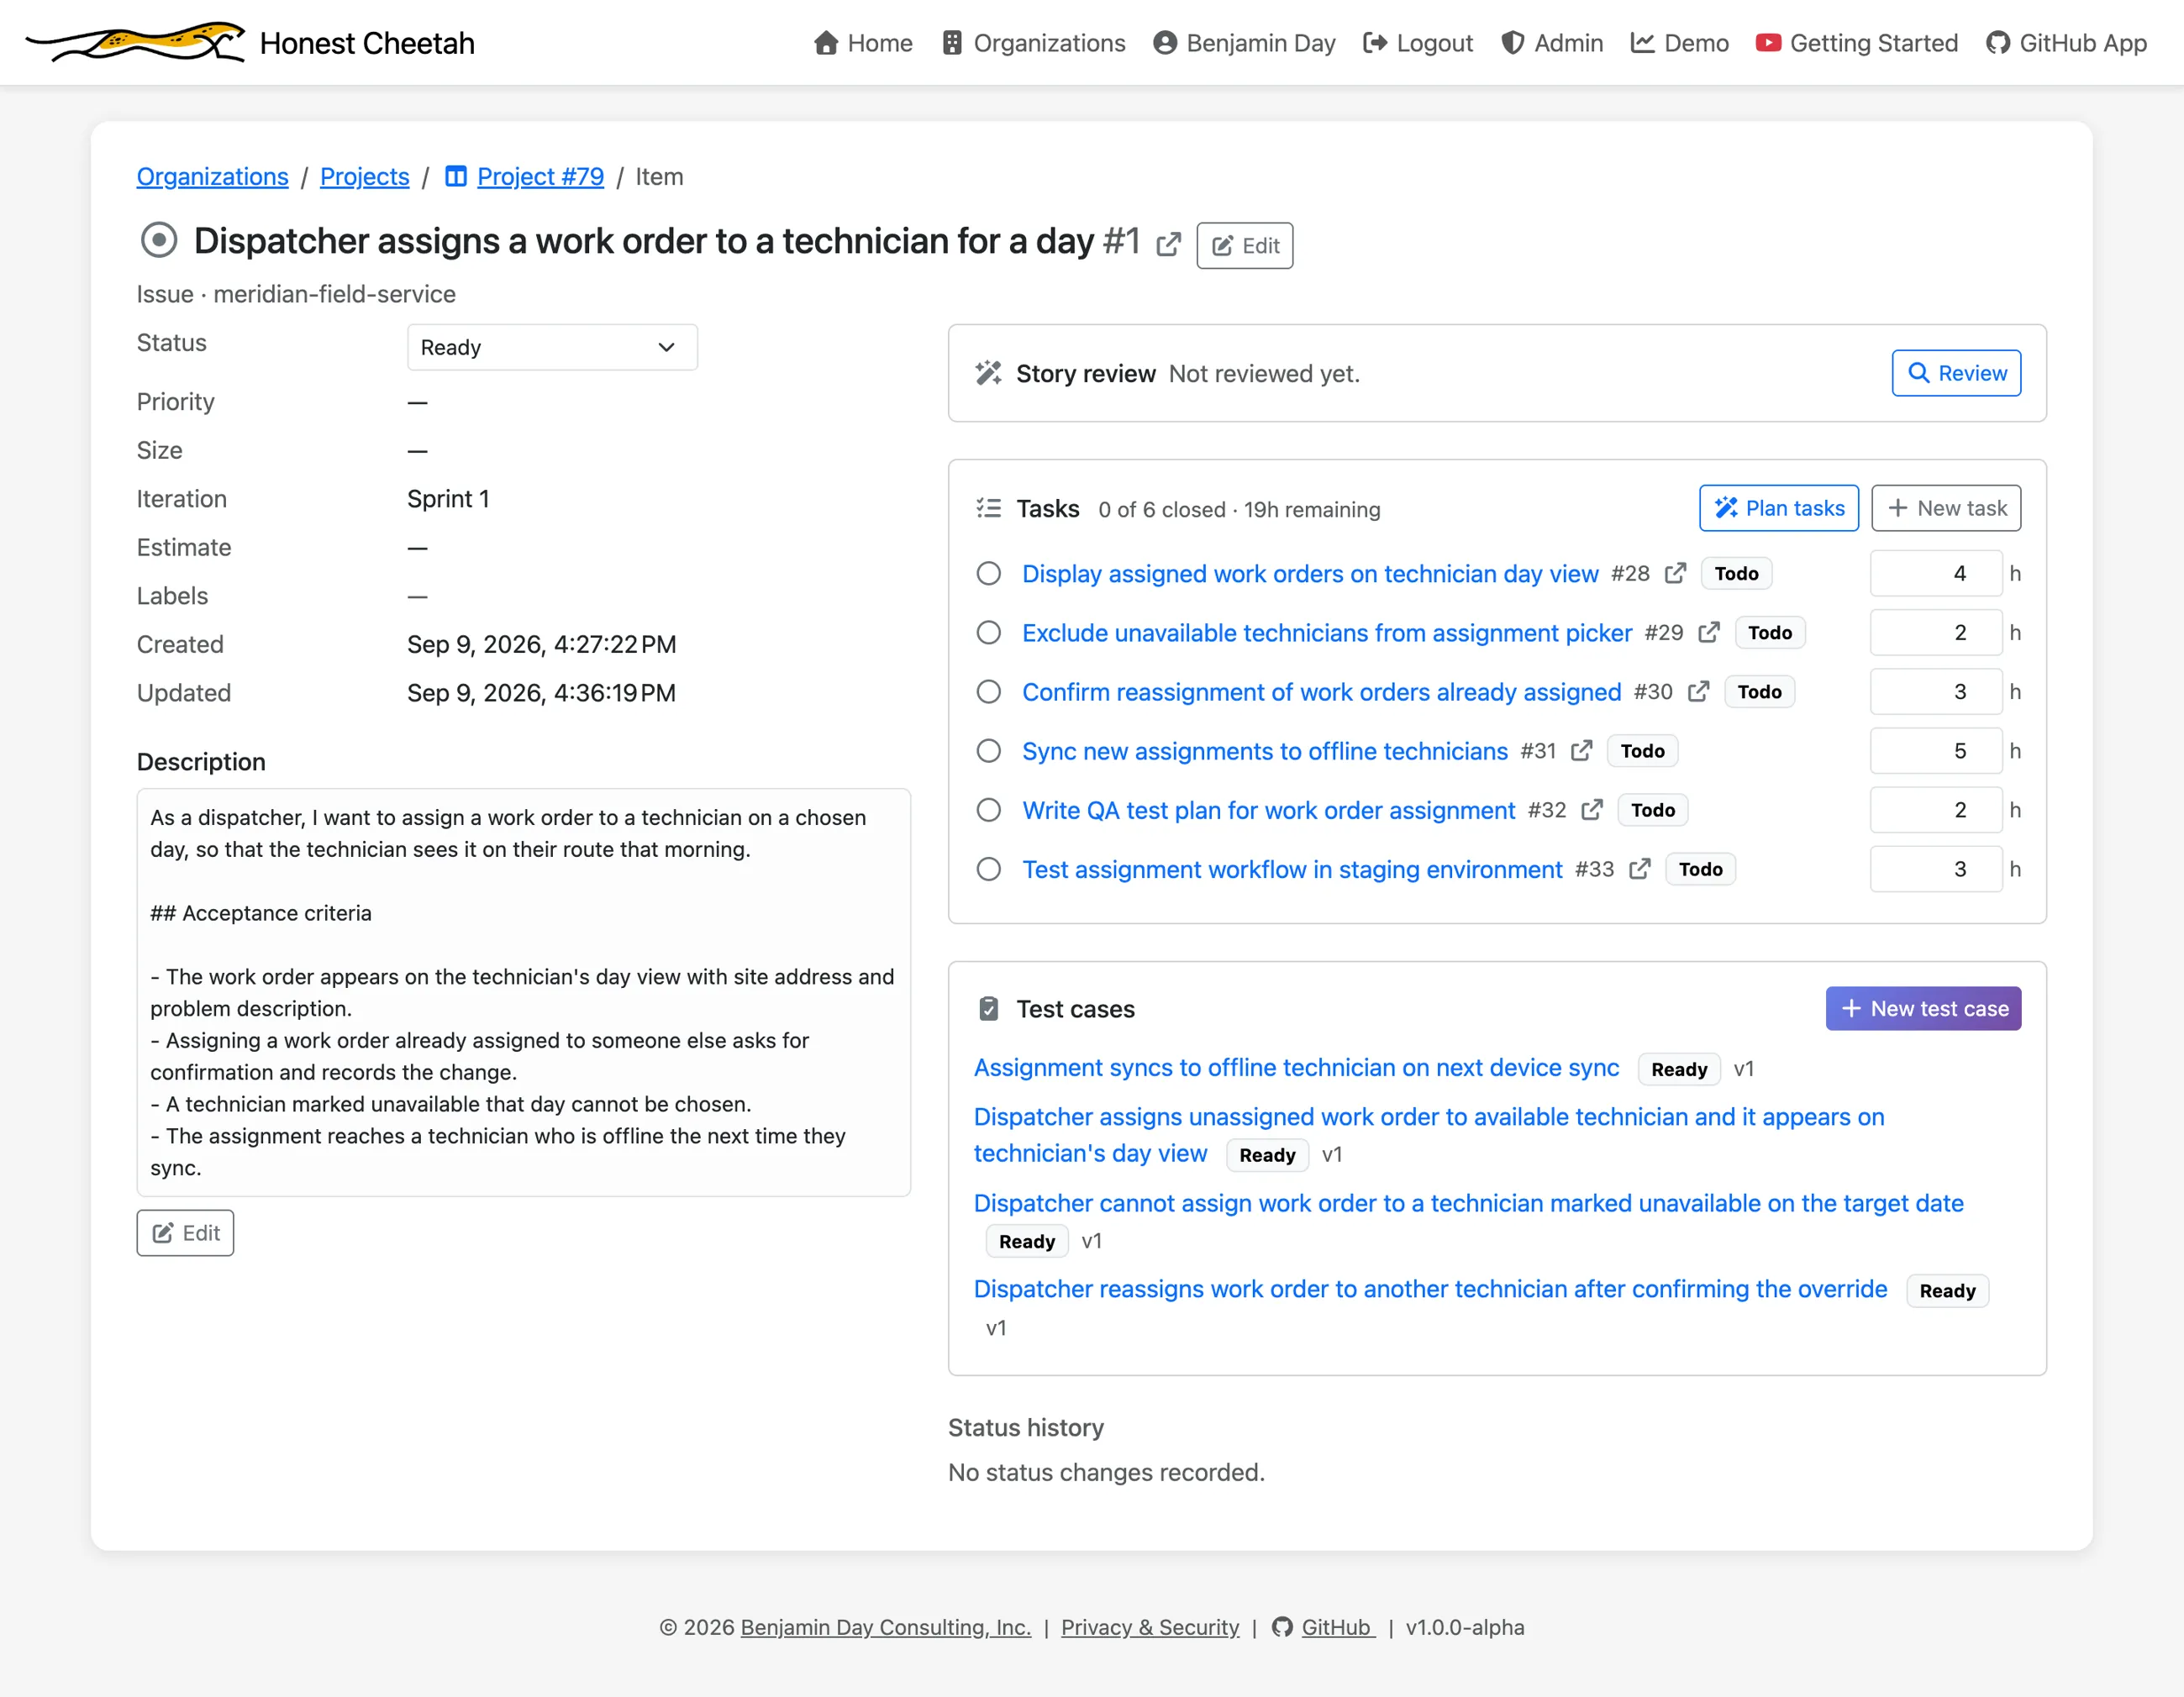
Cases have steps, a priority, a lifecycle, tags, and a result history showing every outcome the case has ever produced, which version of the case it was and who did the testing. A case with history can't be deleted; the page tells you why.
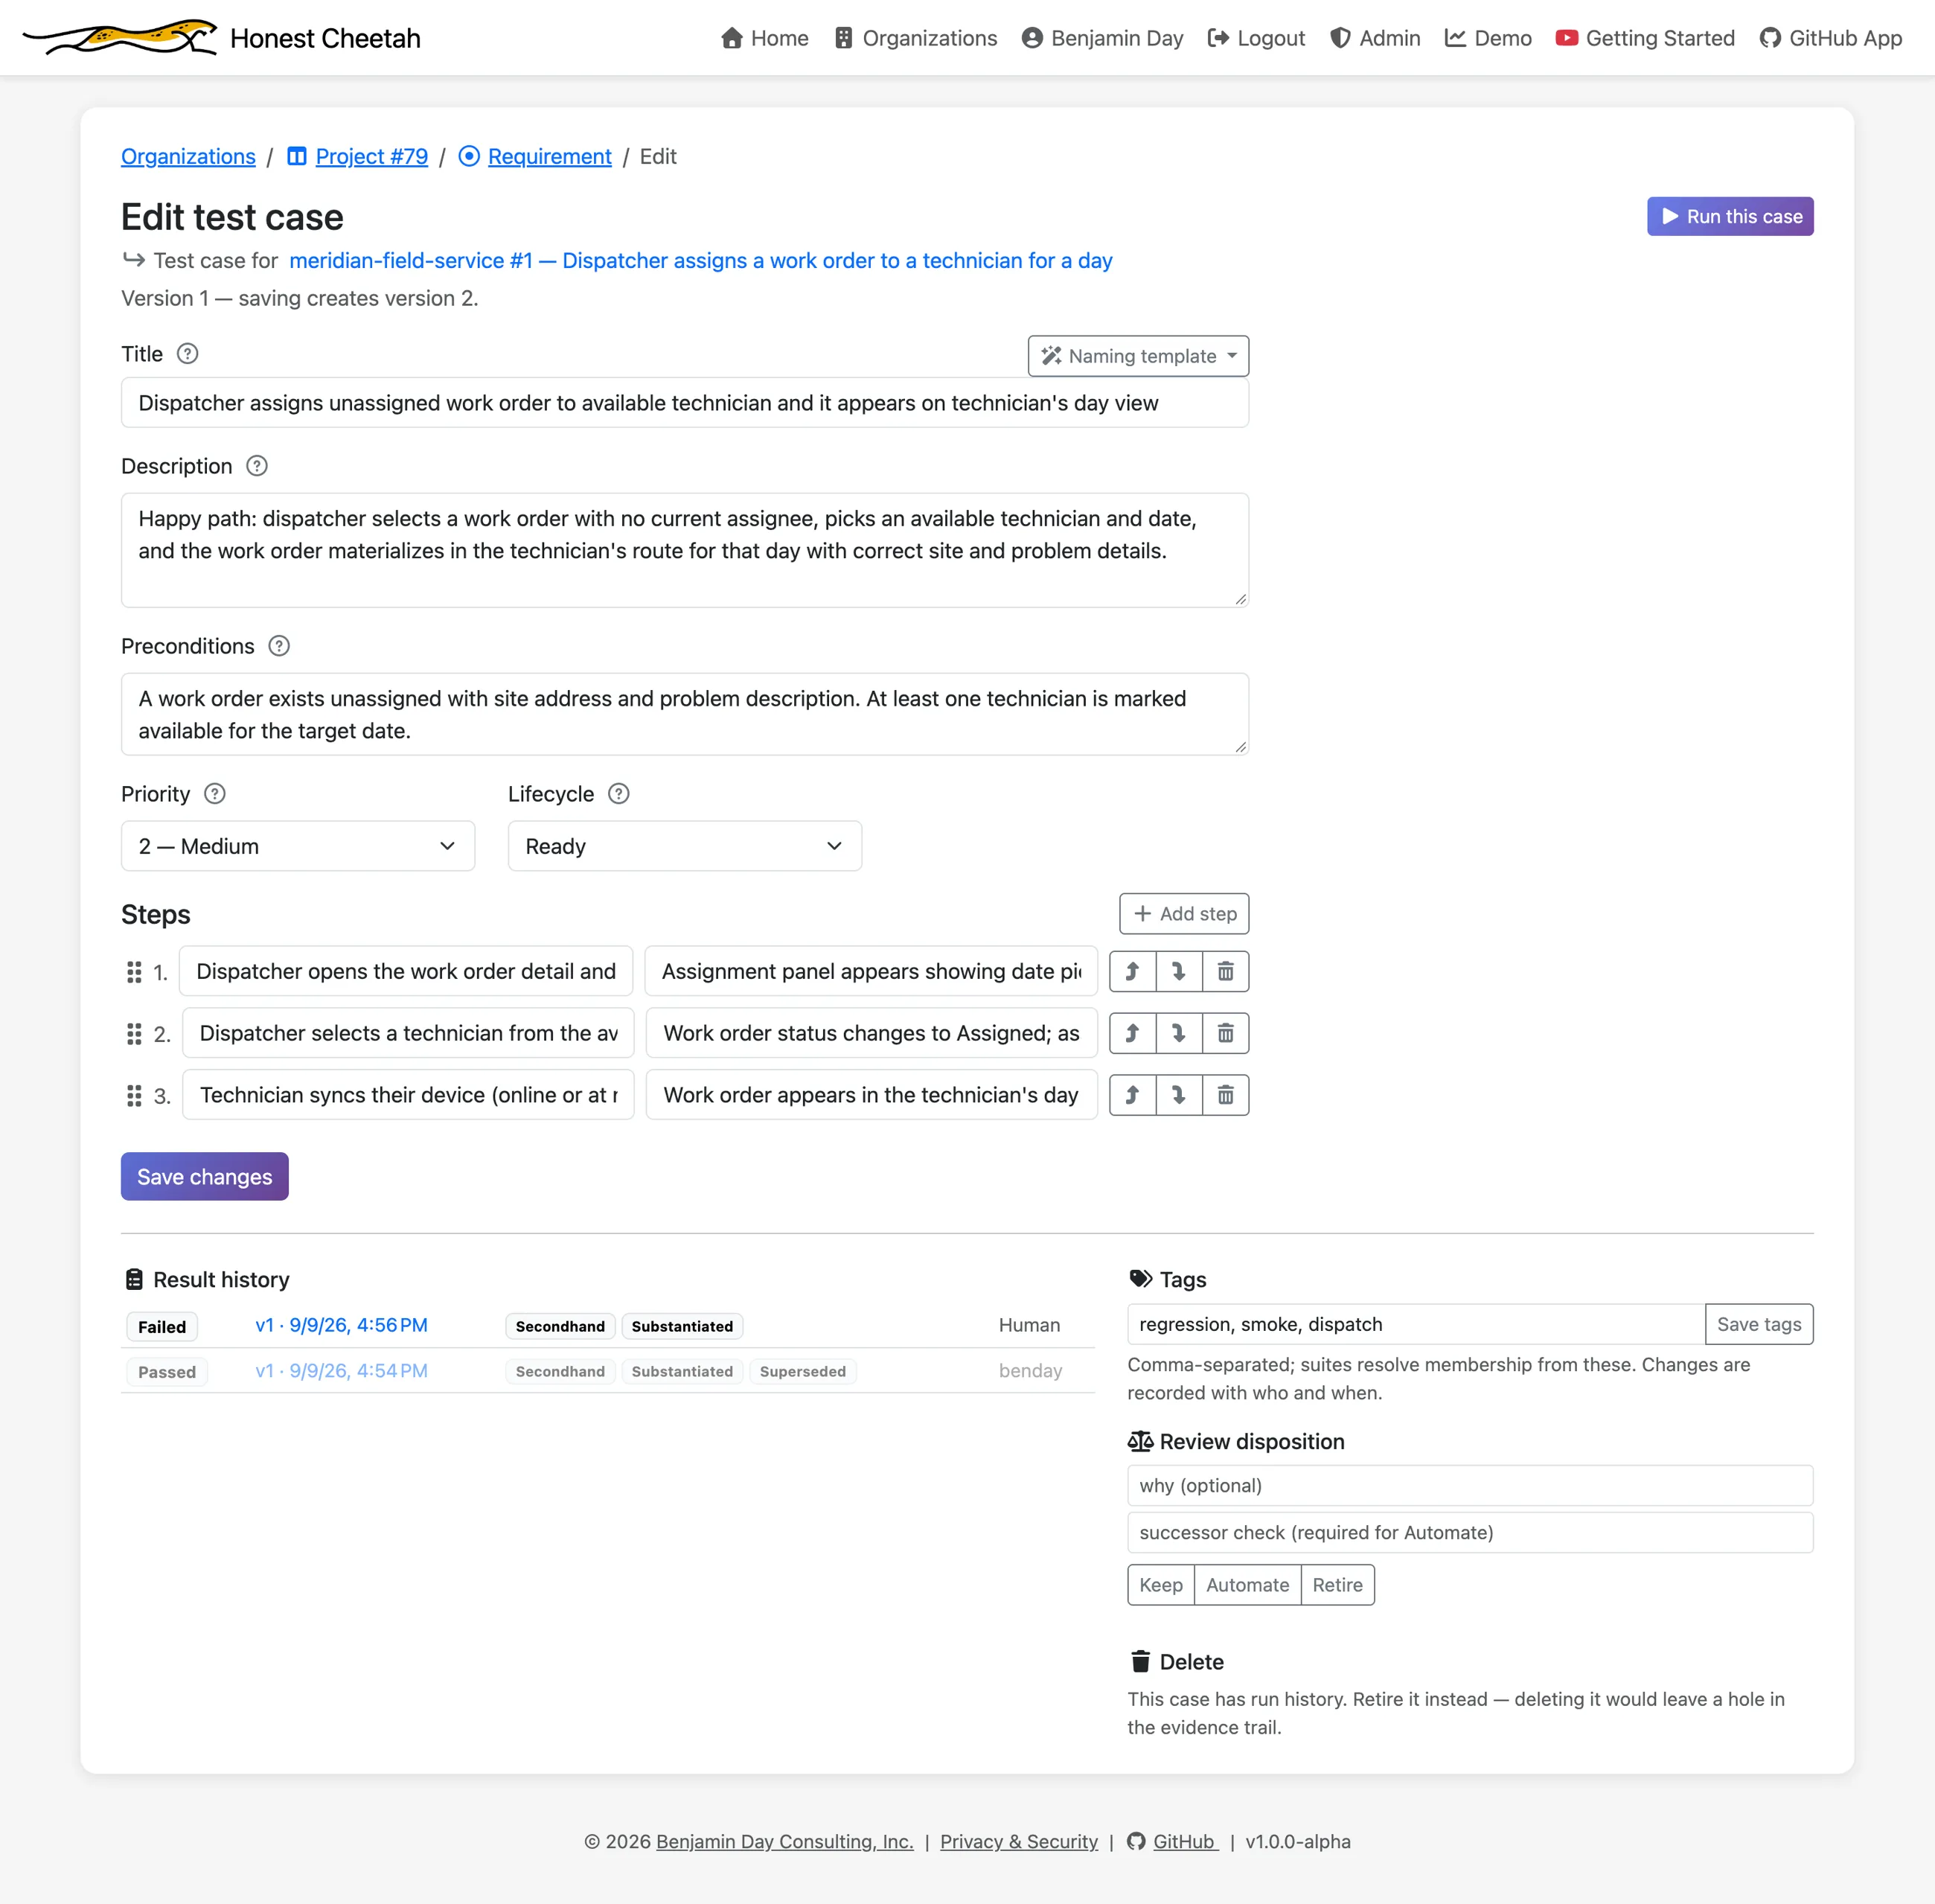
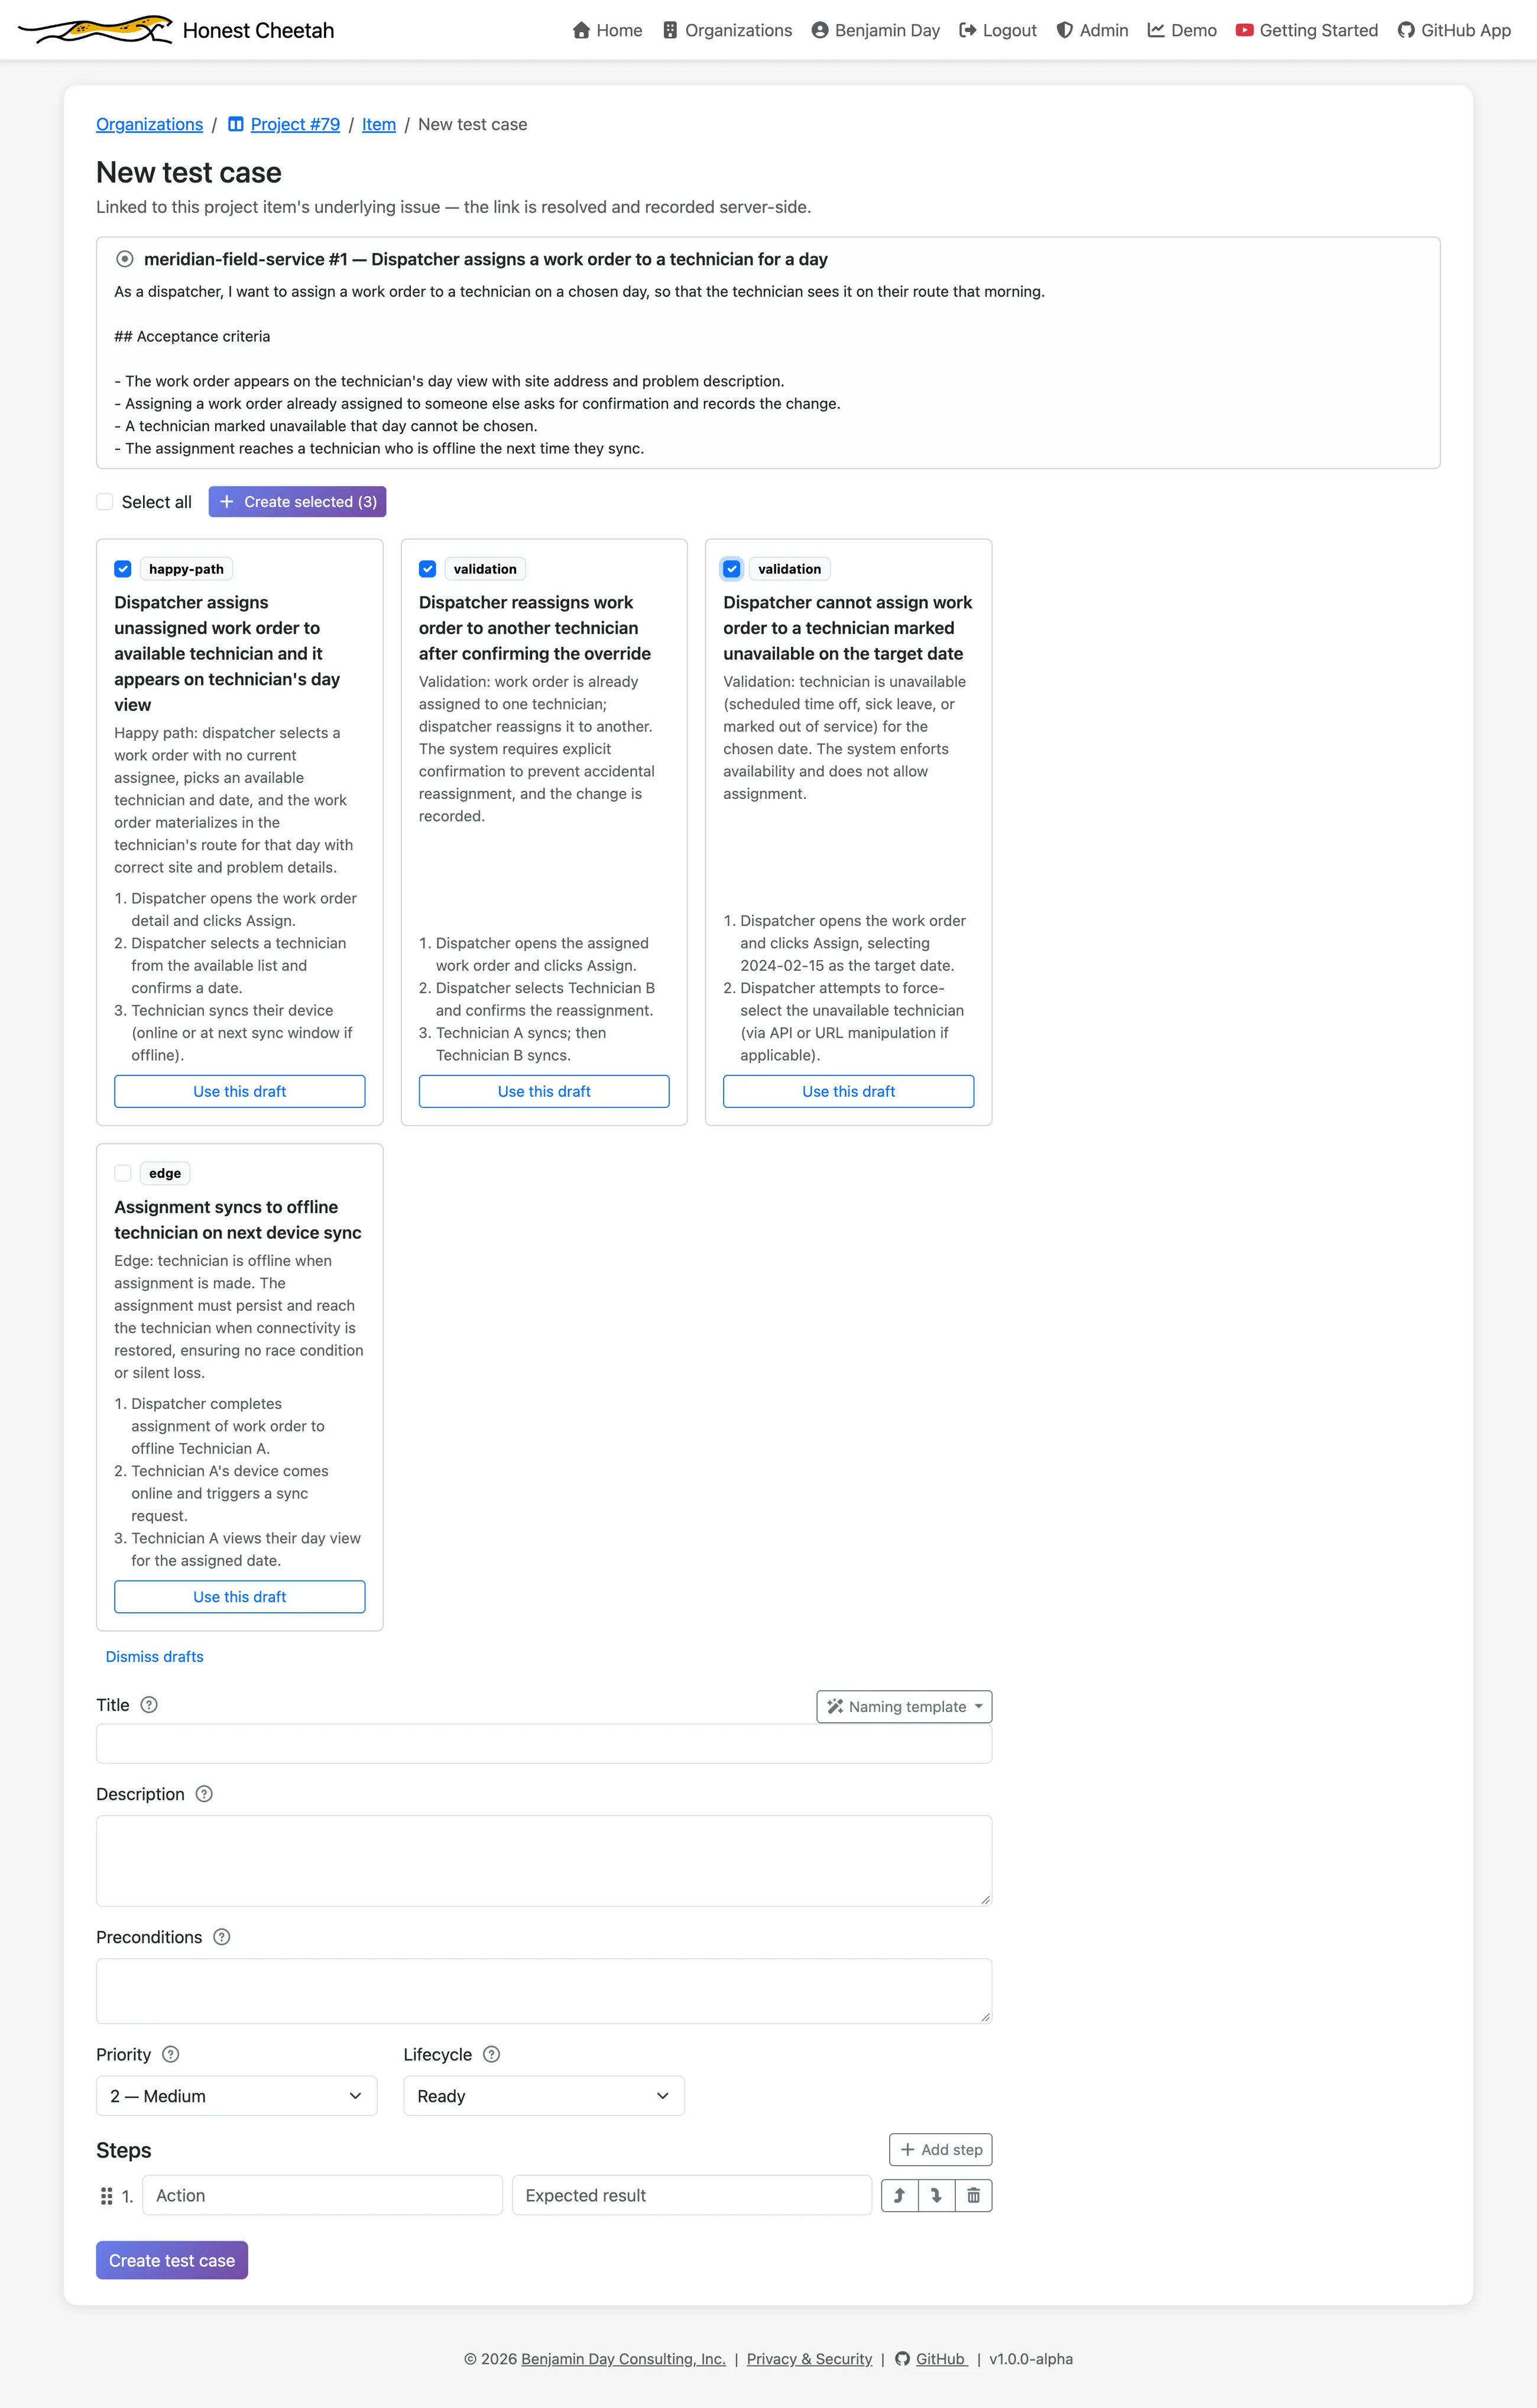
Pick a requirement and click Draft with AI for a handful of proposed cases (happy path, validation, edge), each on a card with a checkbox. Nothing is created until you click Create.
Coming from Azure DevOps Test Plans? The import brings your test cases over with the requirements they belong to.
Suites are tags
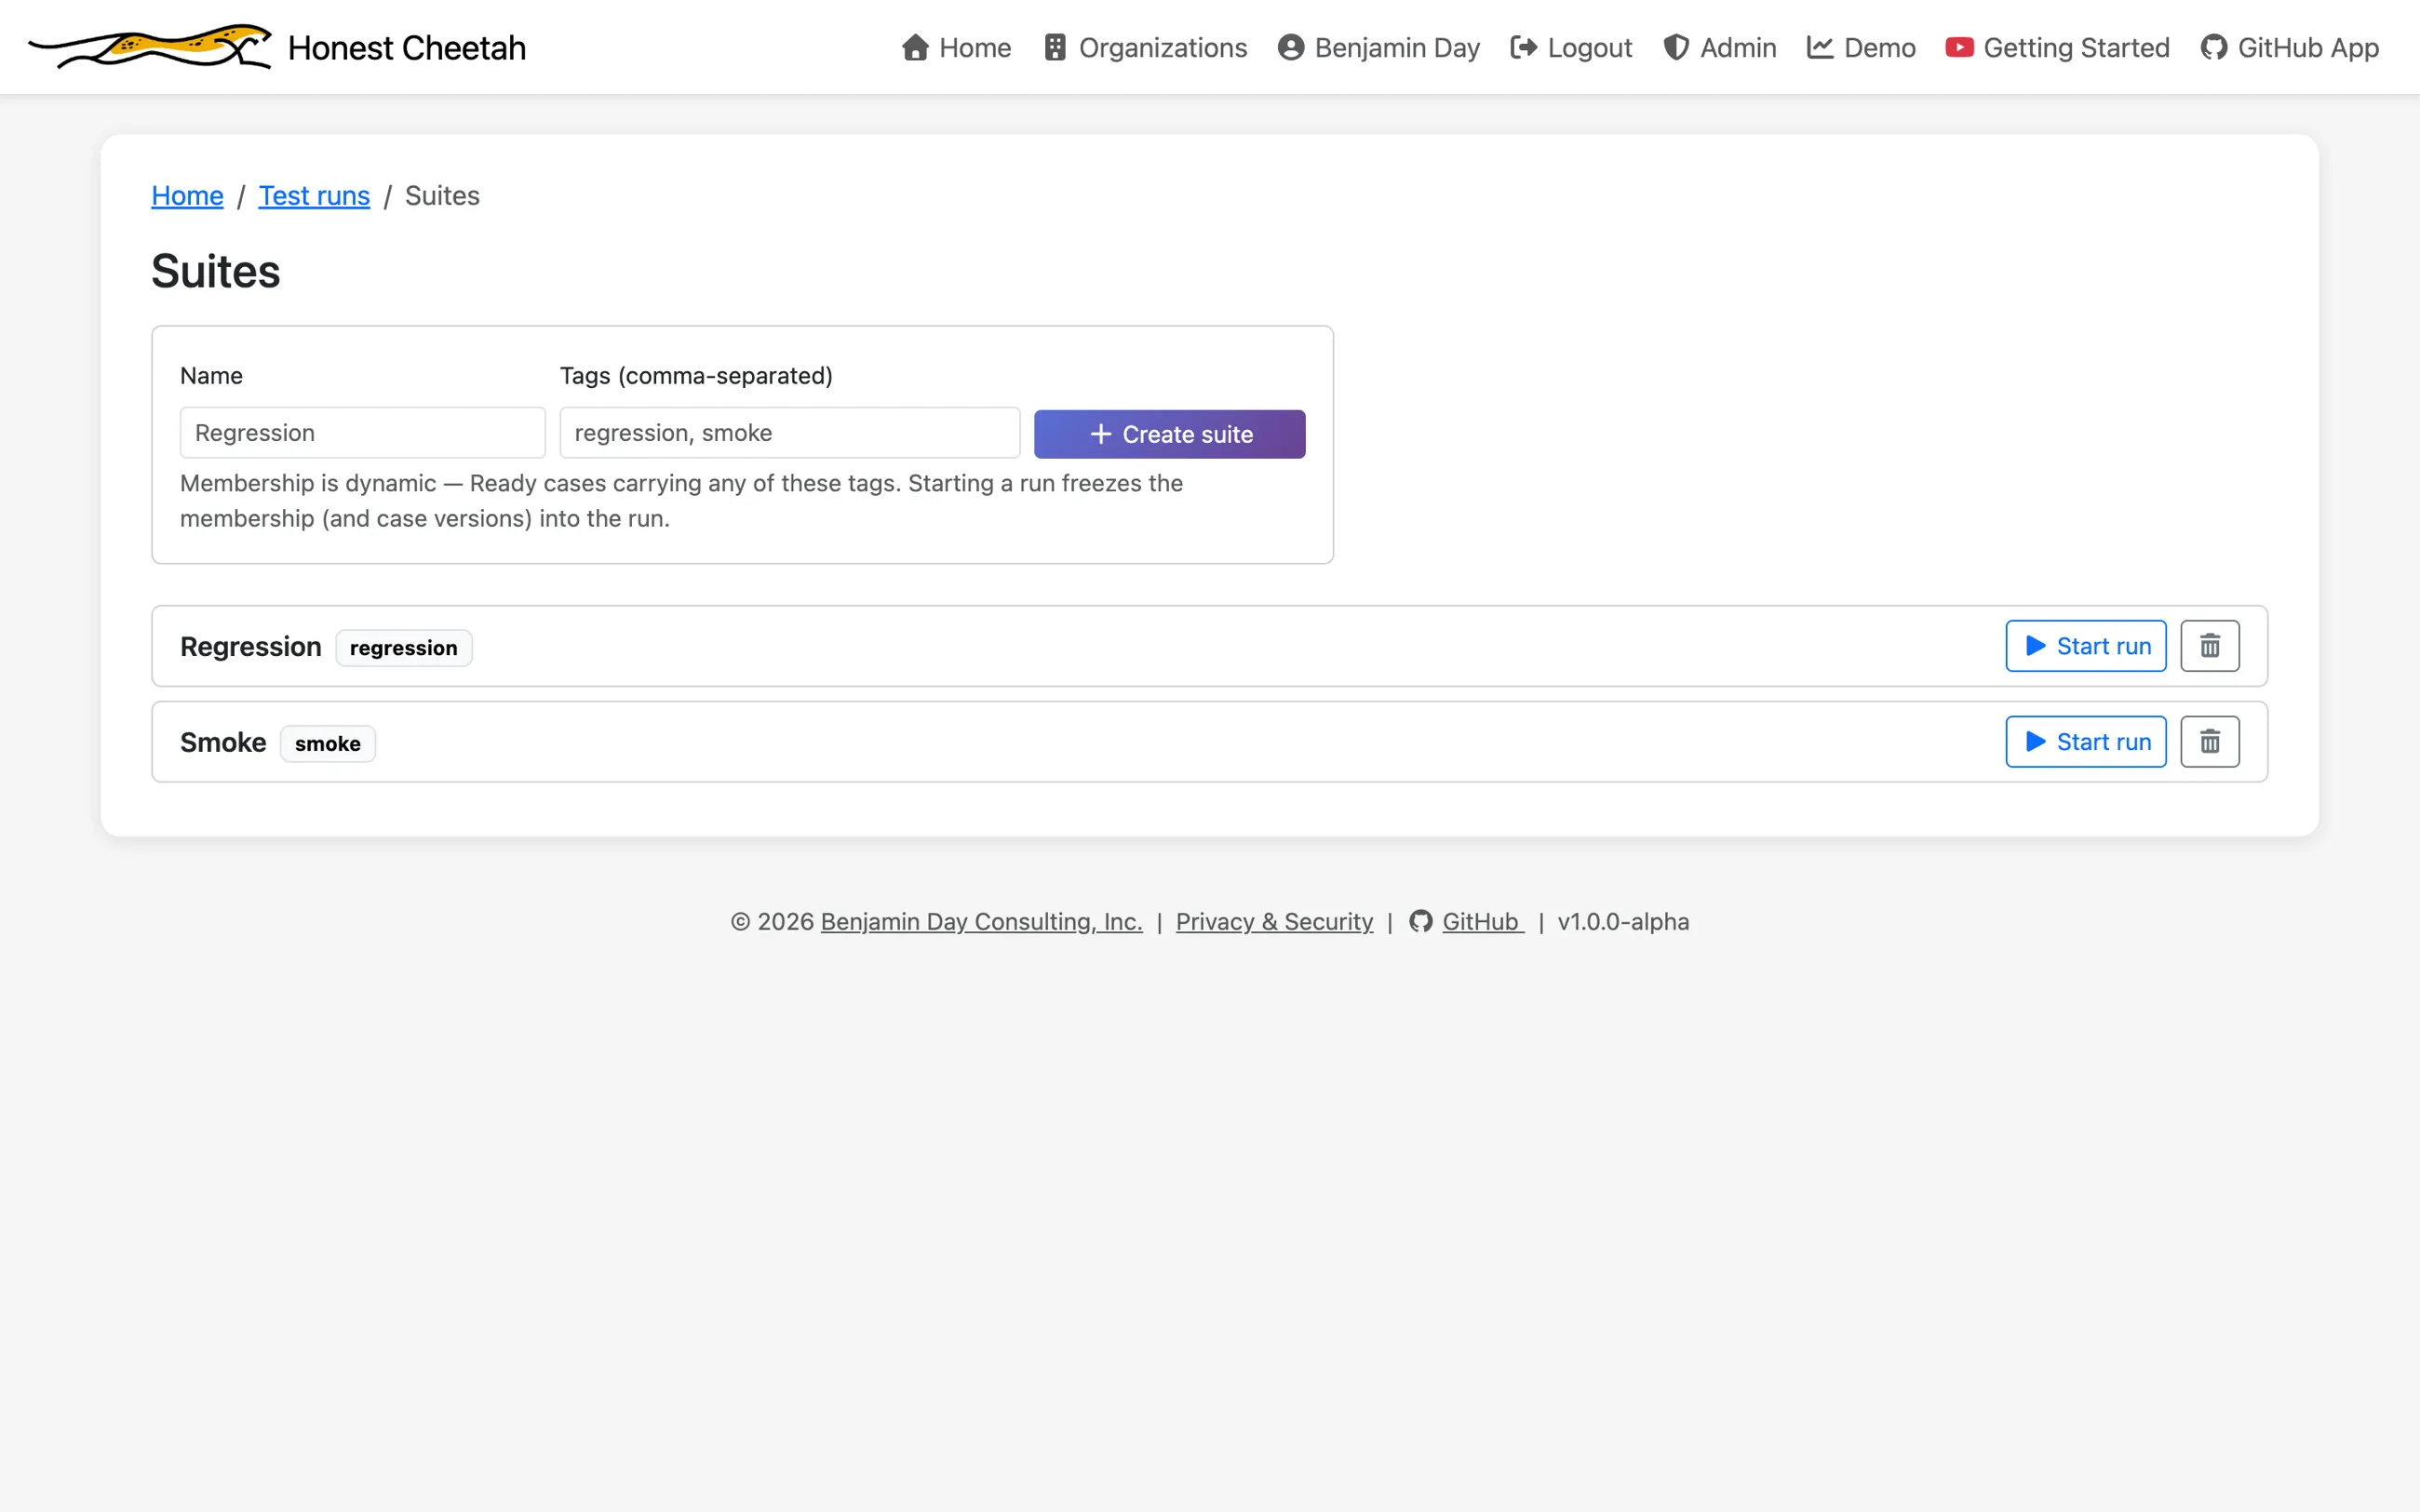
A suite is a name and the tags it matches. Tag cases regression and a suite called Regression picks them up. No membership lists to maintain, and no case that quietly falls out of a suite because someone forgot to add it. Each suite has a Start run button.
Running a test
When you start a run, the first question is what are you testing? Pick a GitHub Actions workflow run, a pull request, or type in an environment or address. Or leave it unattached, which is allowed and labelled as such.
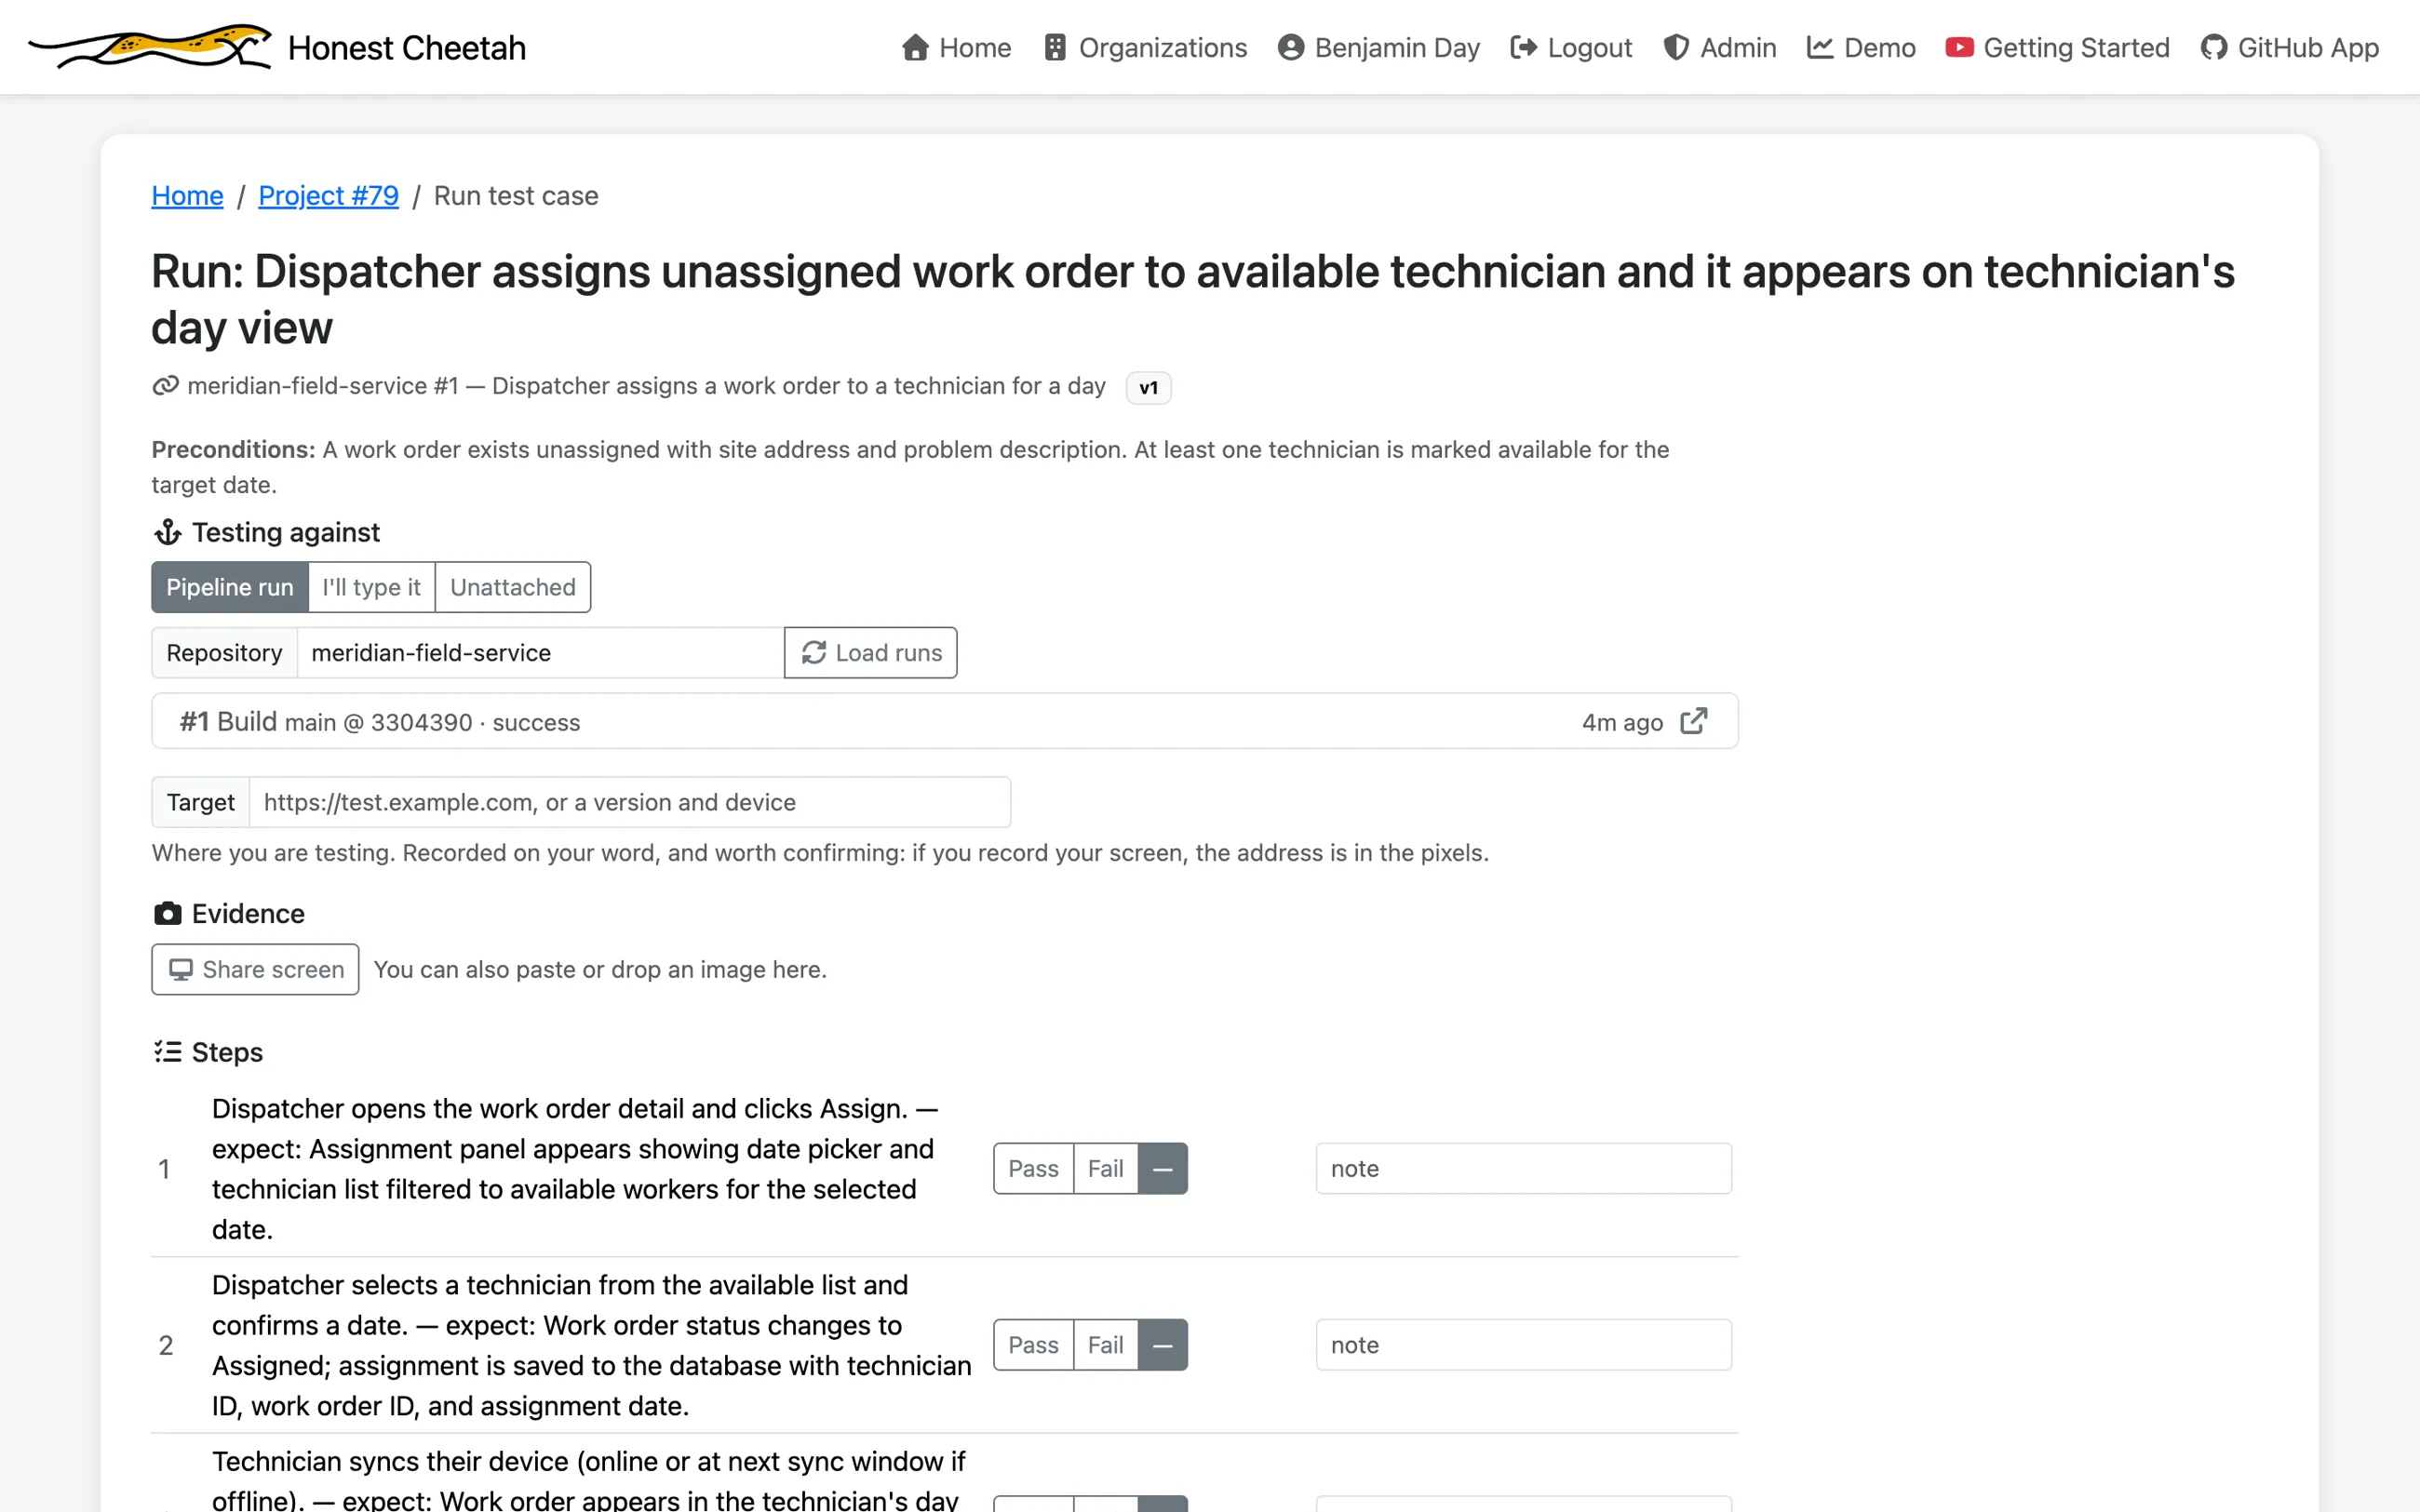
For each result you record who performed it (a human, an agent or an automation, by name), the outcome and notes. While you work, paste or drop screenshots onto the step you're on, or share your screen and let Honest Cheetah capture them. If you allow a recording, it gets a marker at each step so you can play back just the part that matters.
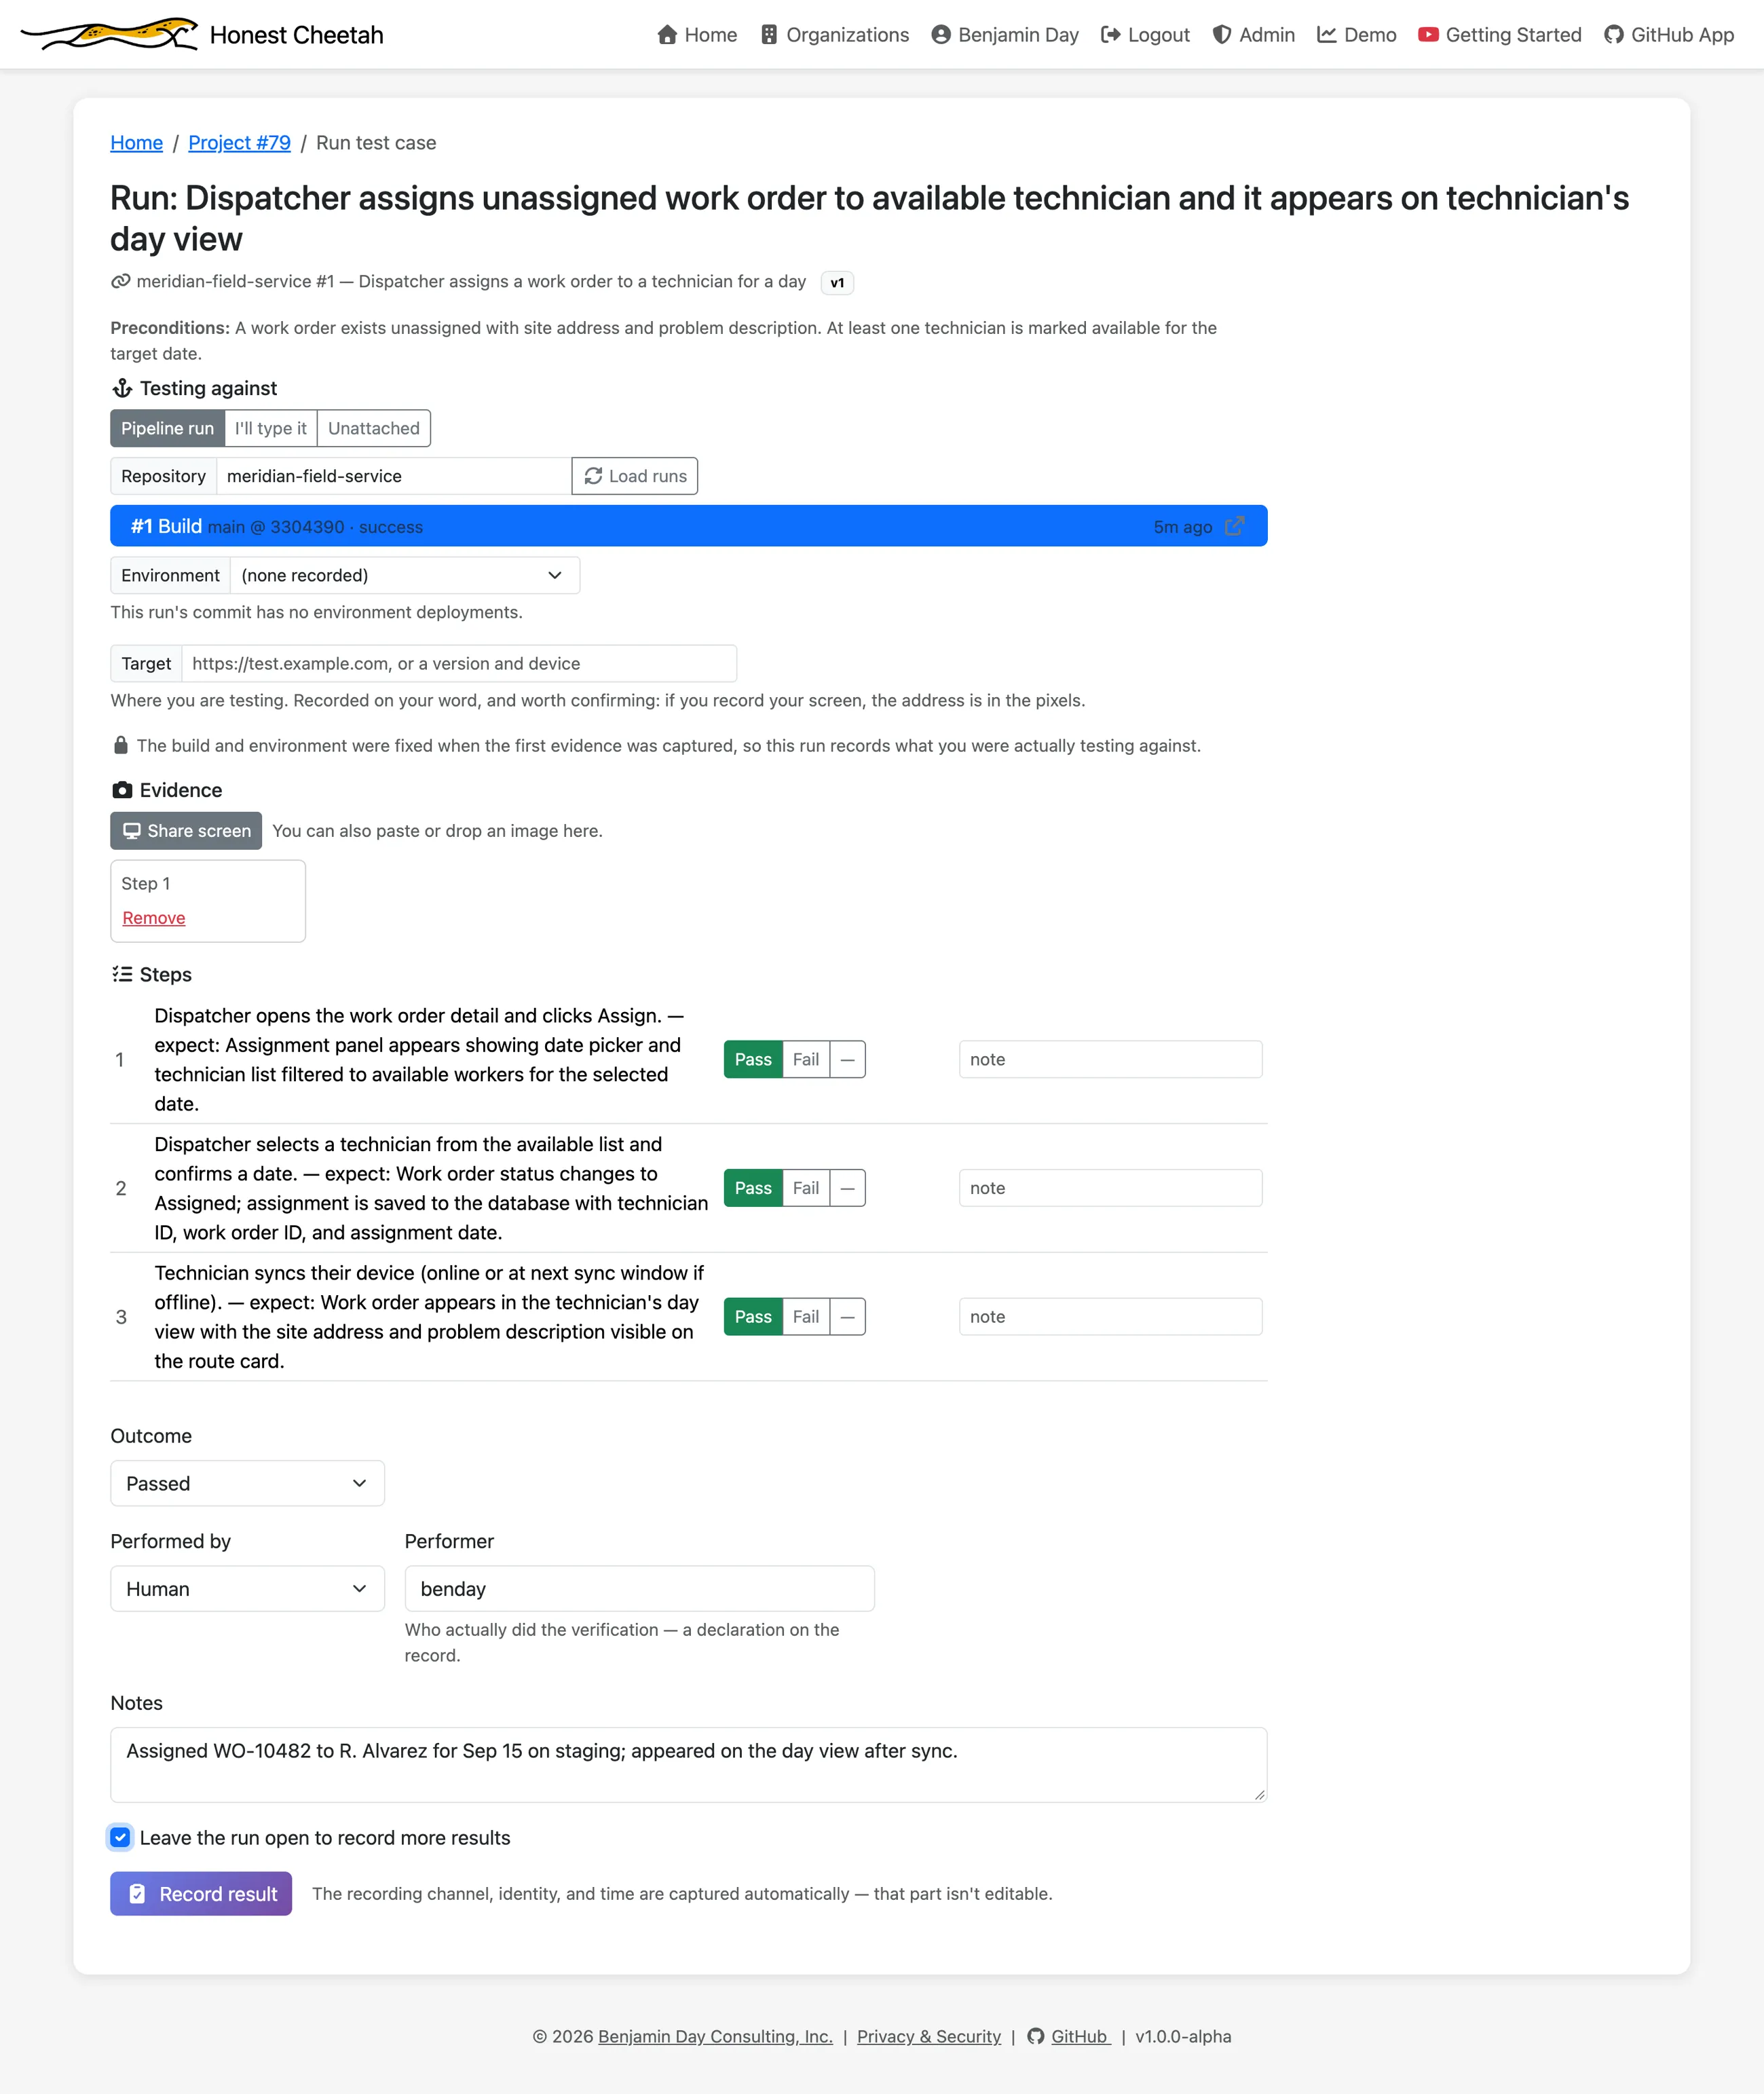
Not everything worth testing has a script. Exploratory test uses the same runner: say what you checked, record the result, and you get the same record, evidence and labels as a scripted case.
File a bug from the failure
A failed result has a File a bug button. The form opens under the result, prefilled with the test case, the step, the run and links to the evidence. Submit, and it's a Bug issue on your board, linked back to the run.
Keep, automate, retire
Every case has a review disposition. Mark it Keep, Automate or Retire, and the suite you run by hand every sprint gets shorter on purpose instead of by neglect.
Who tested what? The chain of custody.
An agent writes the code. An agent writes the tests. An agent runs them and reports green. Everything looks exactly like it did two years ago, except now you can't tell "a senior engineer tested this on staging against the release build" from "an agent said it was fine." Both produce a green checkmark.
Git doesn't help: authorship is self-reported, agents commit under human identities, and a signed commit proves someone had the key, not that anyone tested anything. A chain of custody answers four questions about every claim that something works: who verified it, how firsthand that was, against what build, and whether the record can be trusted.
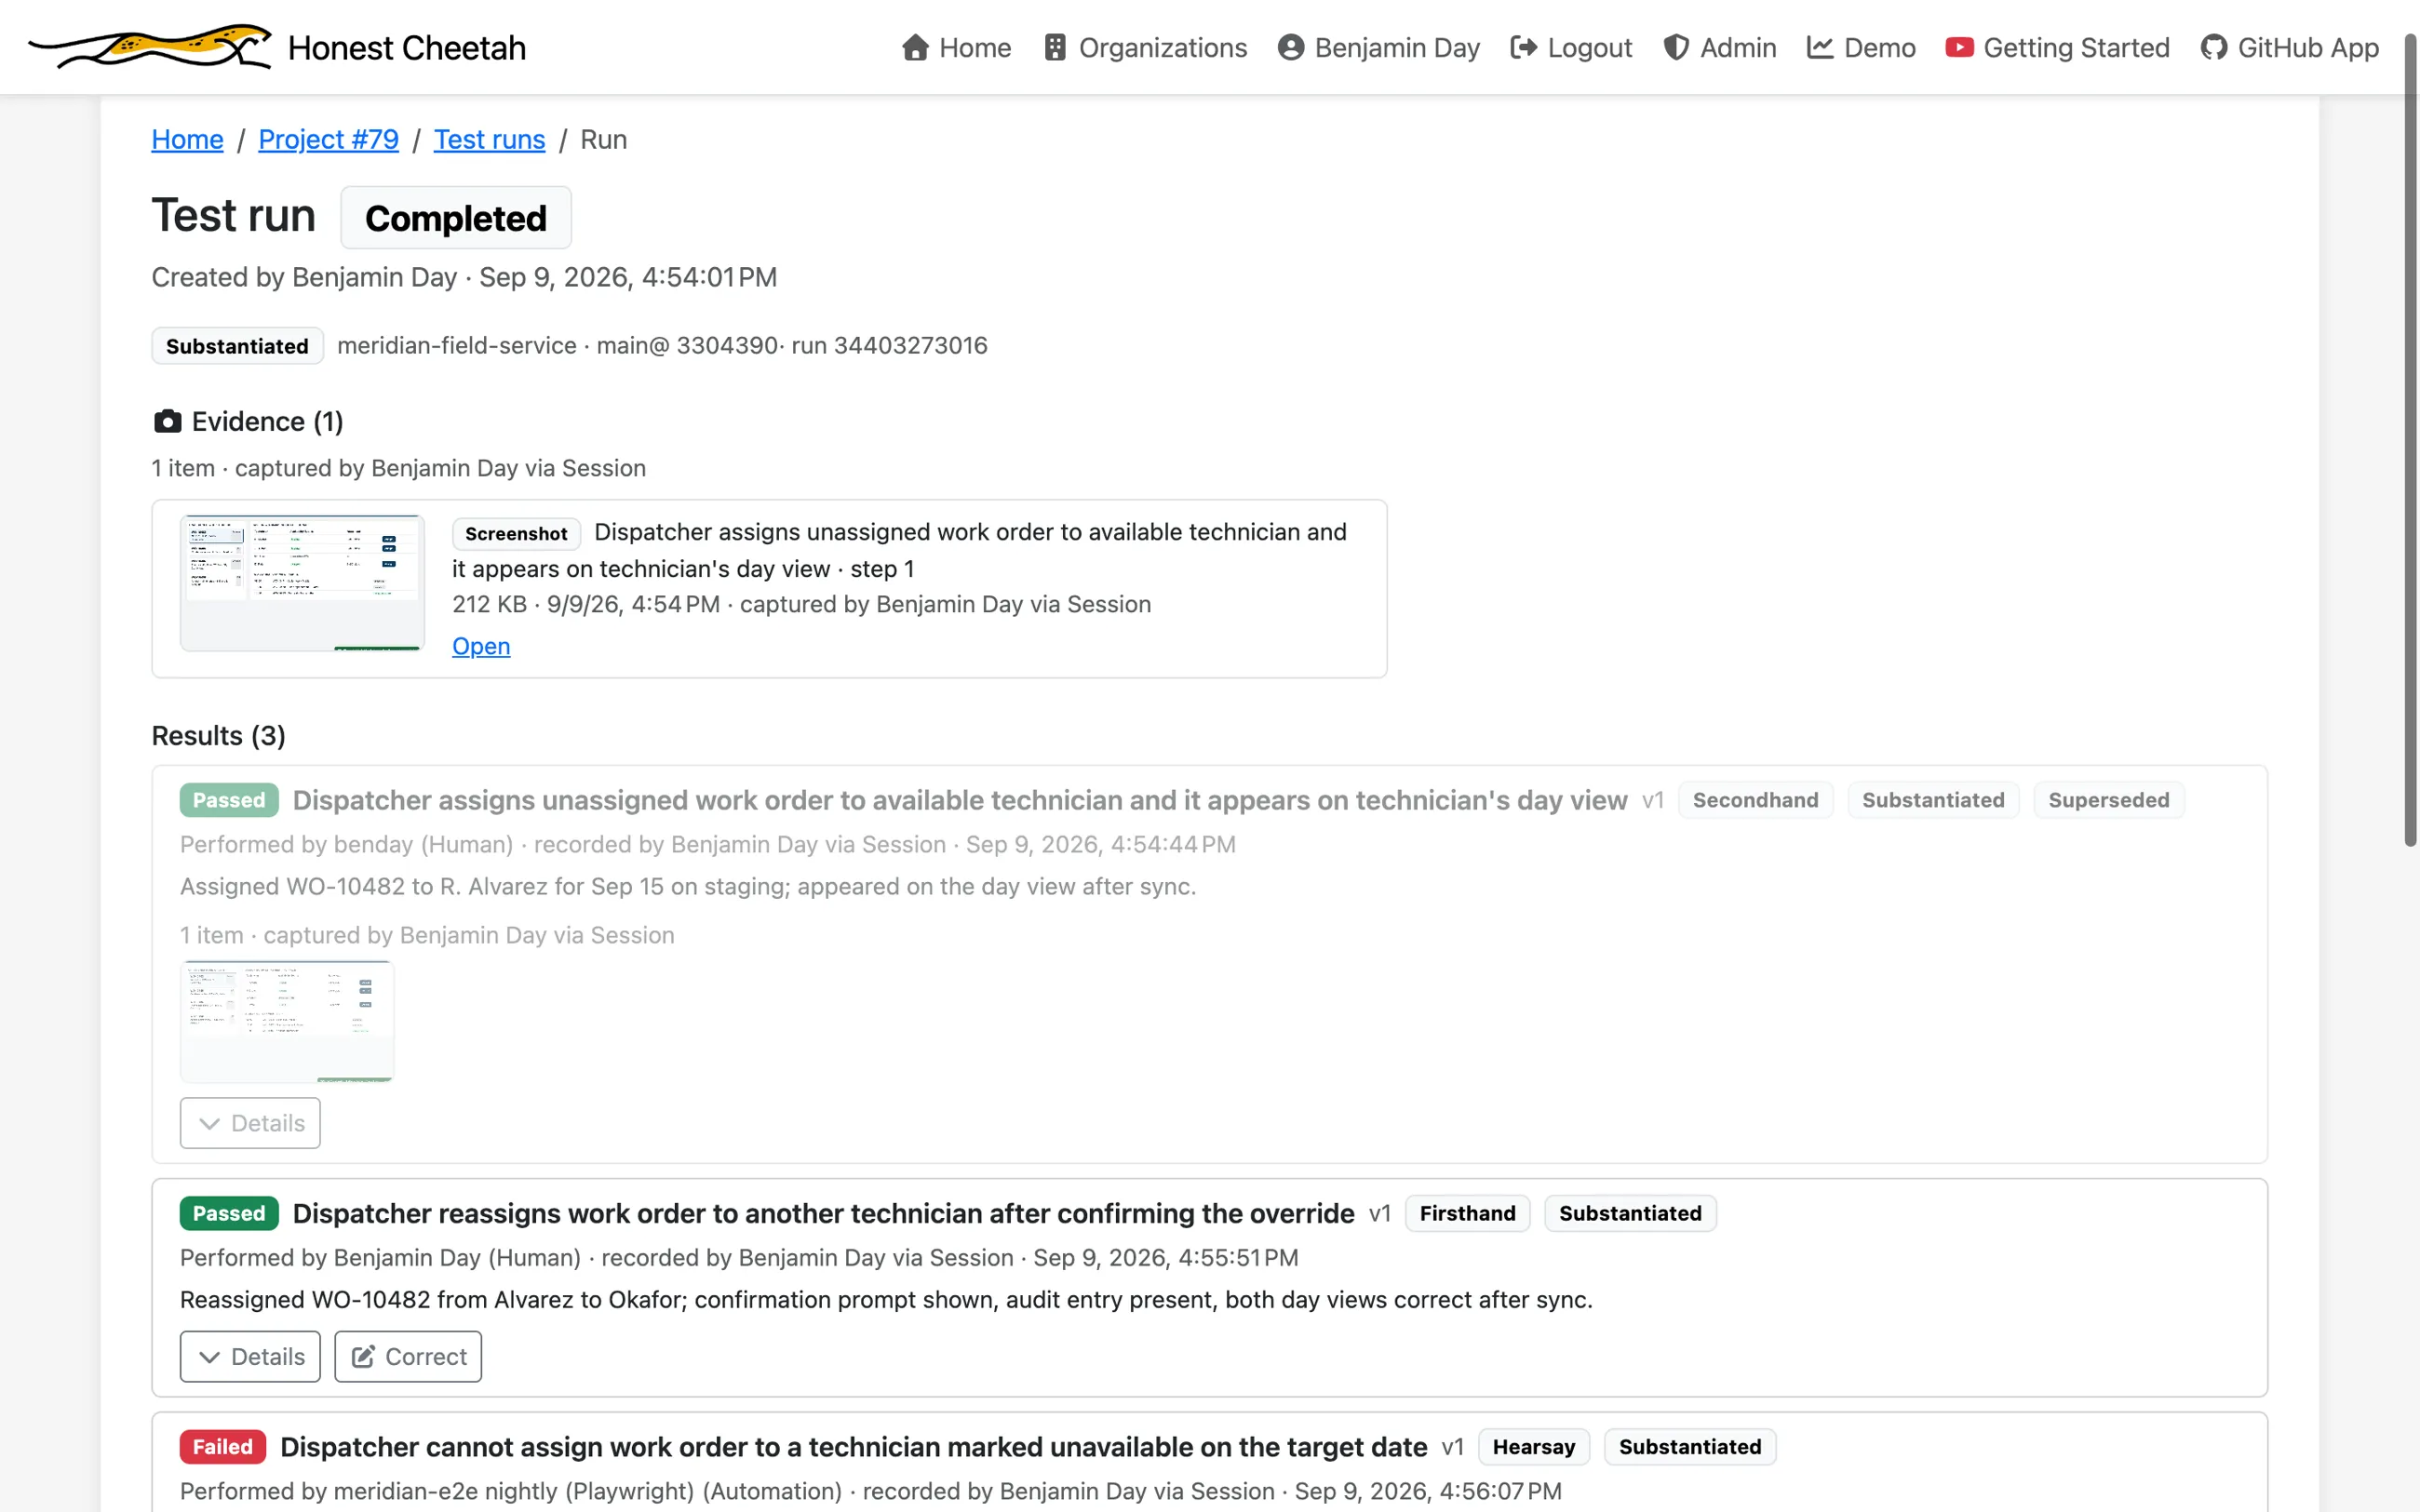
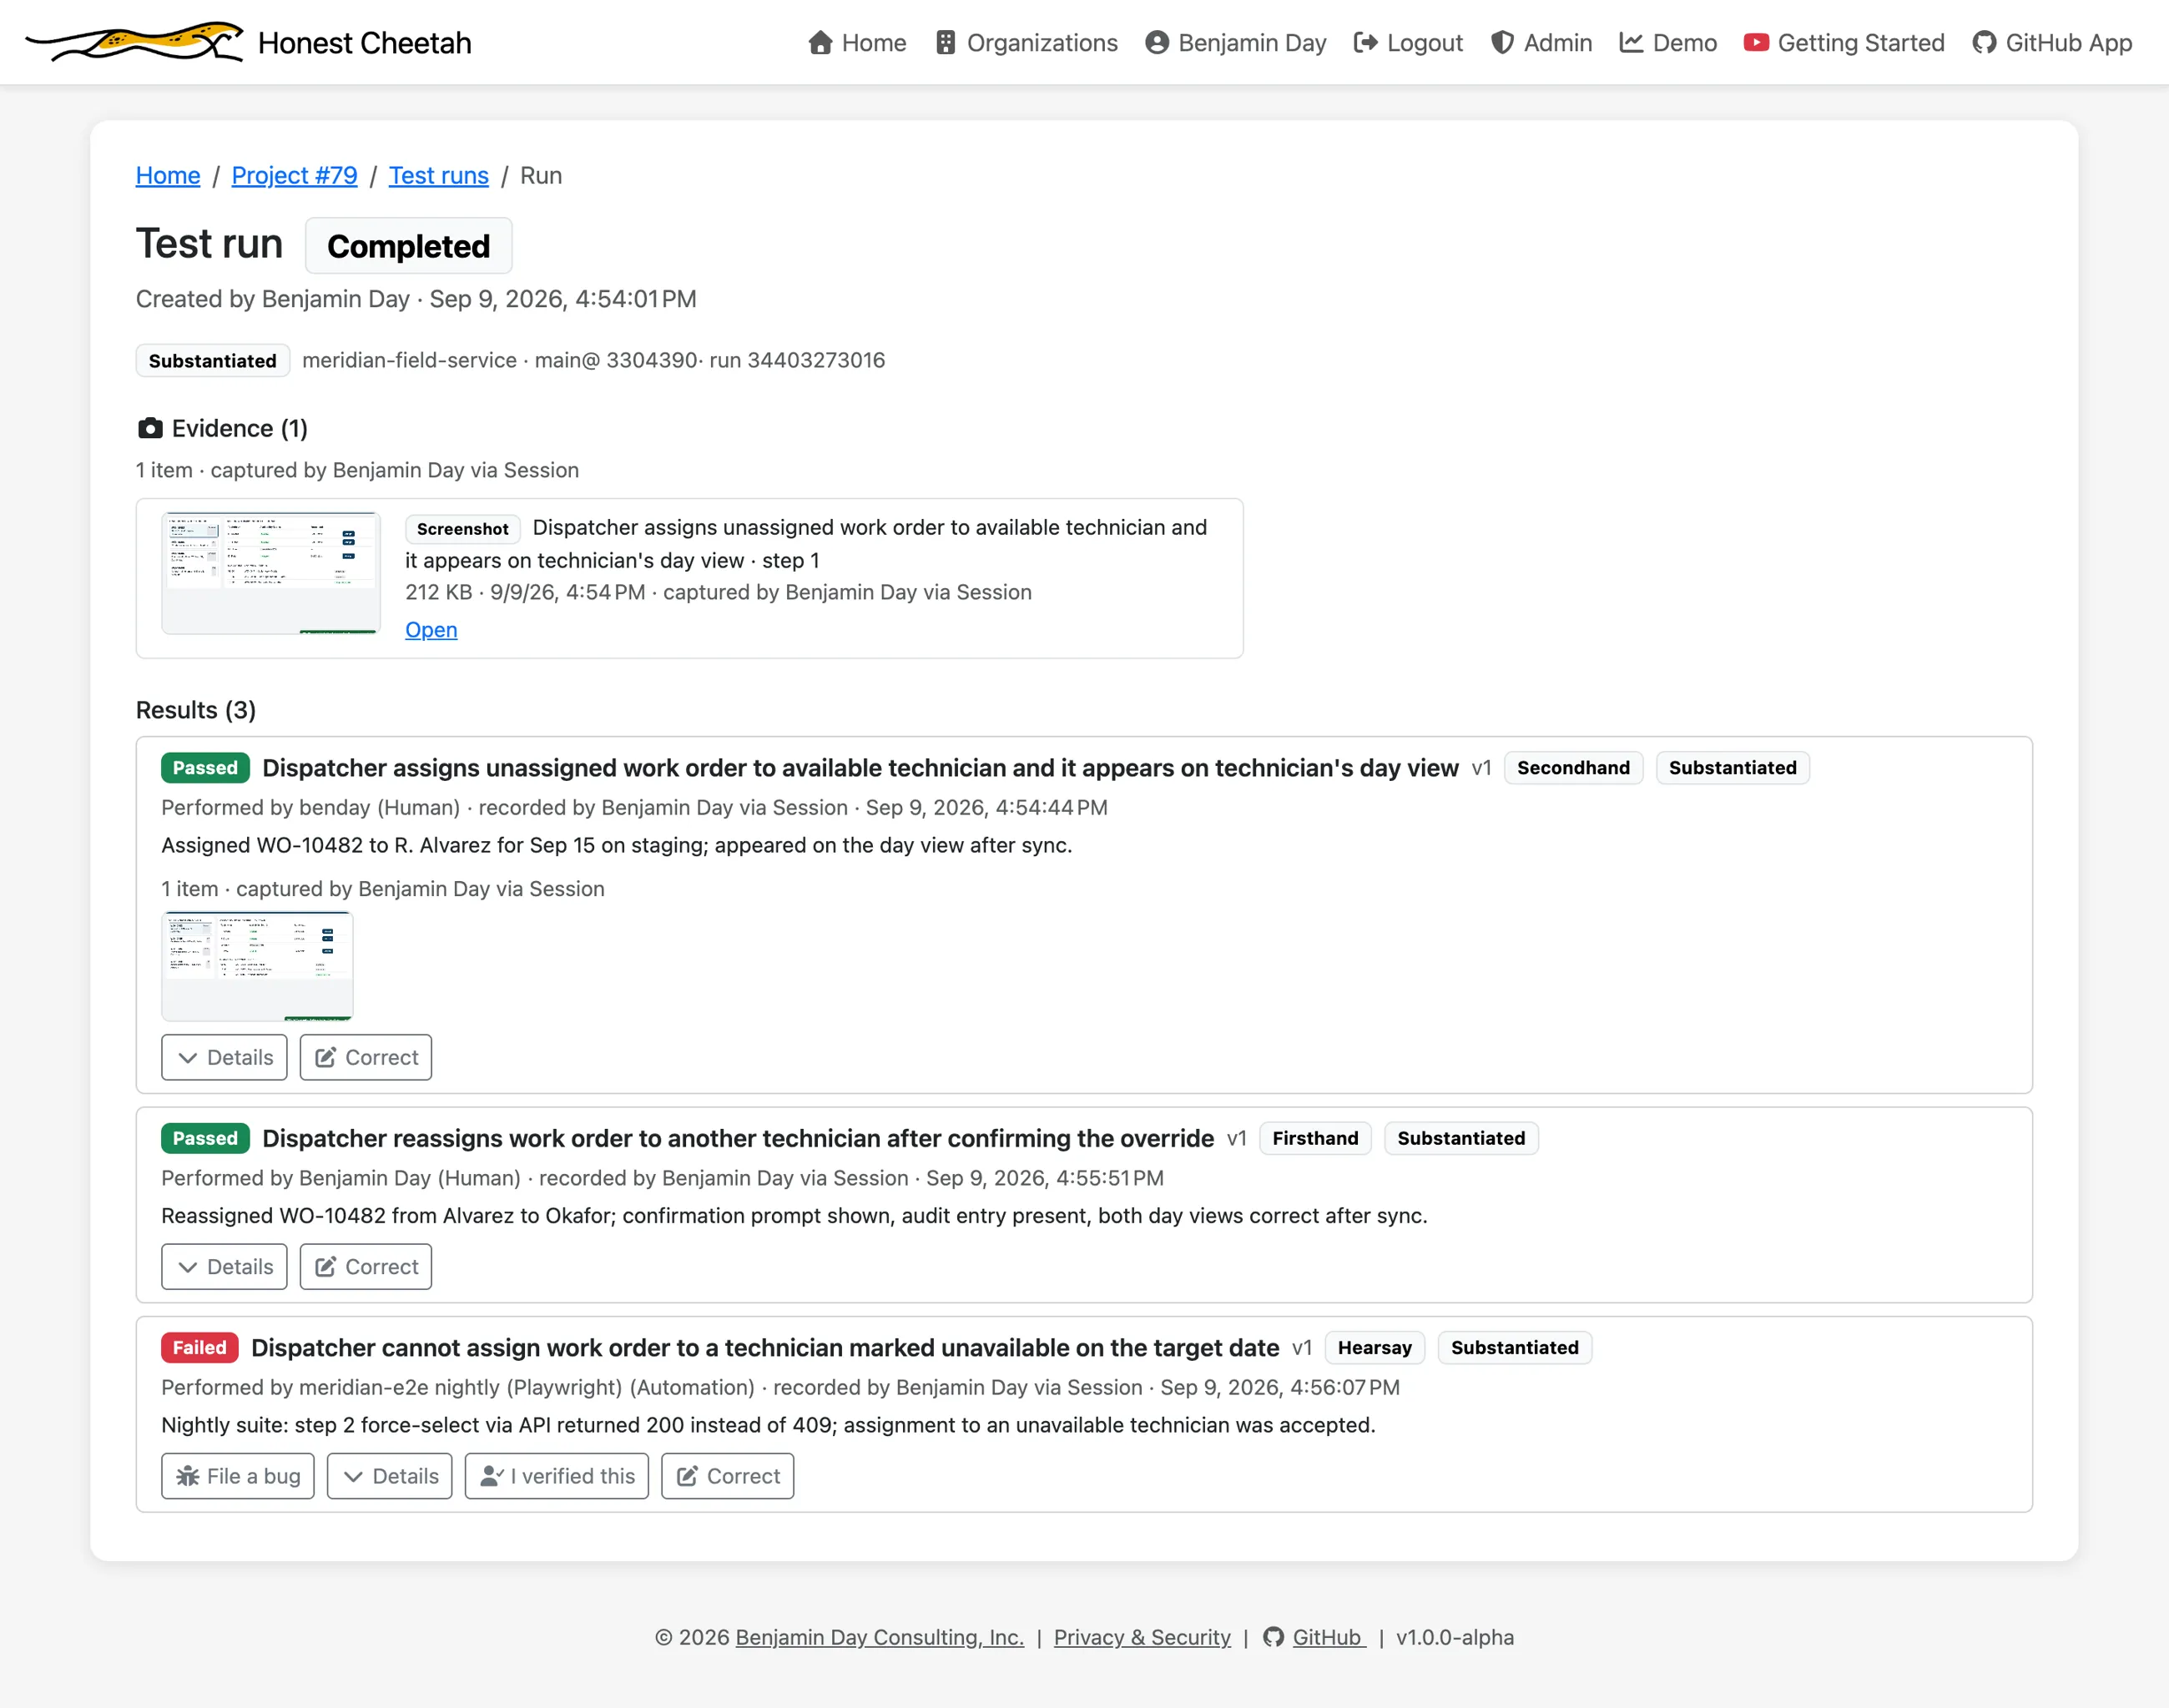
The tester enters the claim. The server records who made it. The tester says who performed the test. Honest Cheetah stamps who recorded the result, when, and through which channel, and the client can't supply or forge those values. On the page it reads "Performed by meridian-e2e nightly (Automation) · recorded by Benjamin Day via Session."
Completed runs are immutable. Nobody edits a finished run: not the tester, not the admin, not the agent. A correction is its own run that says why and points back at the result it supersedes. The original stays where it was, dimmed and marked Superseded.
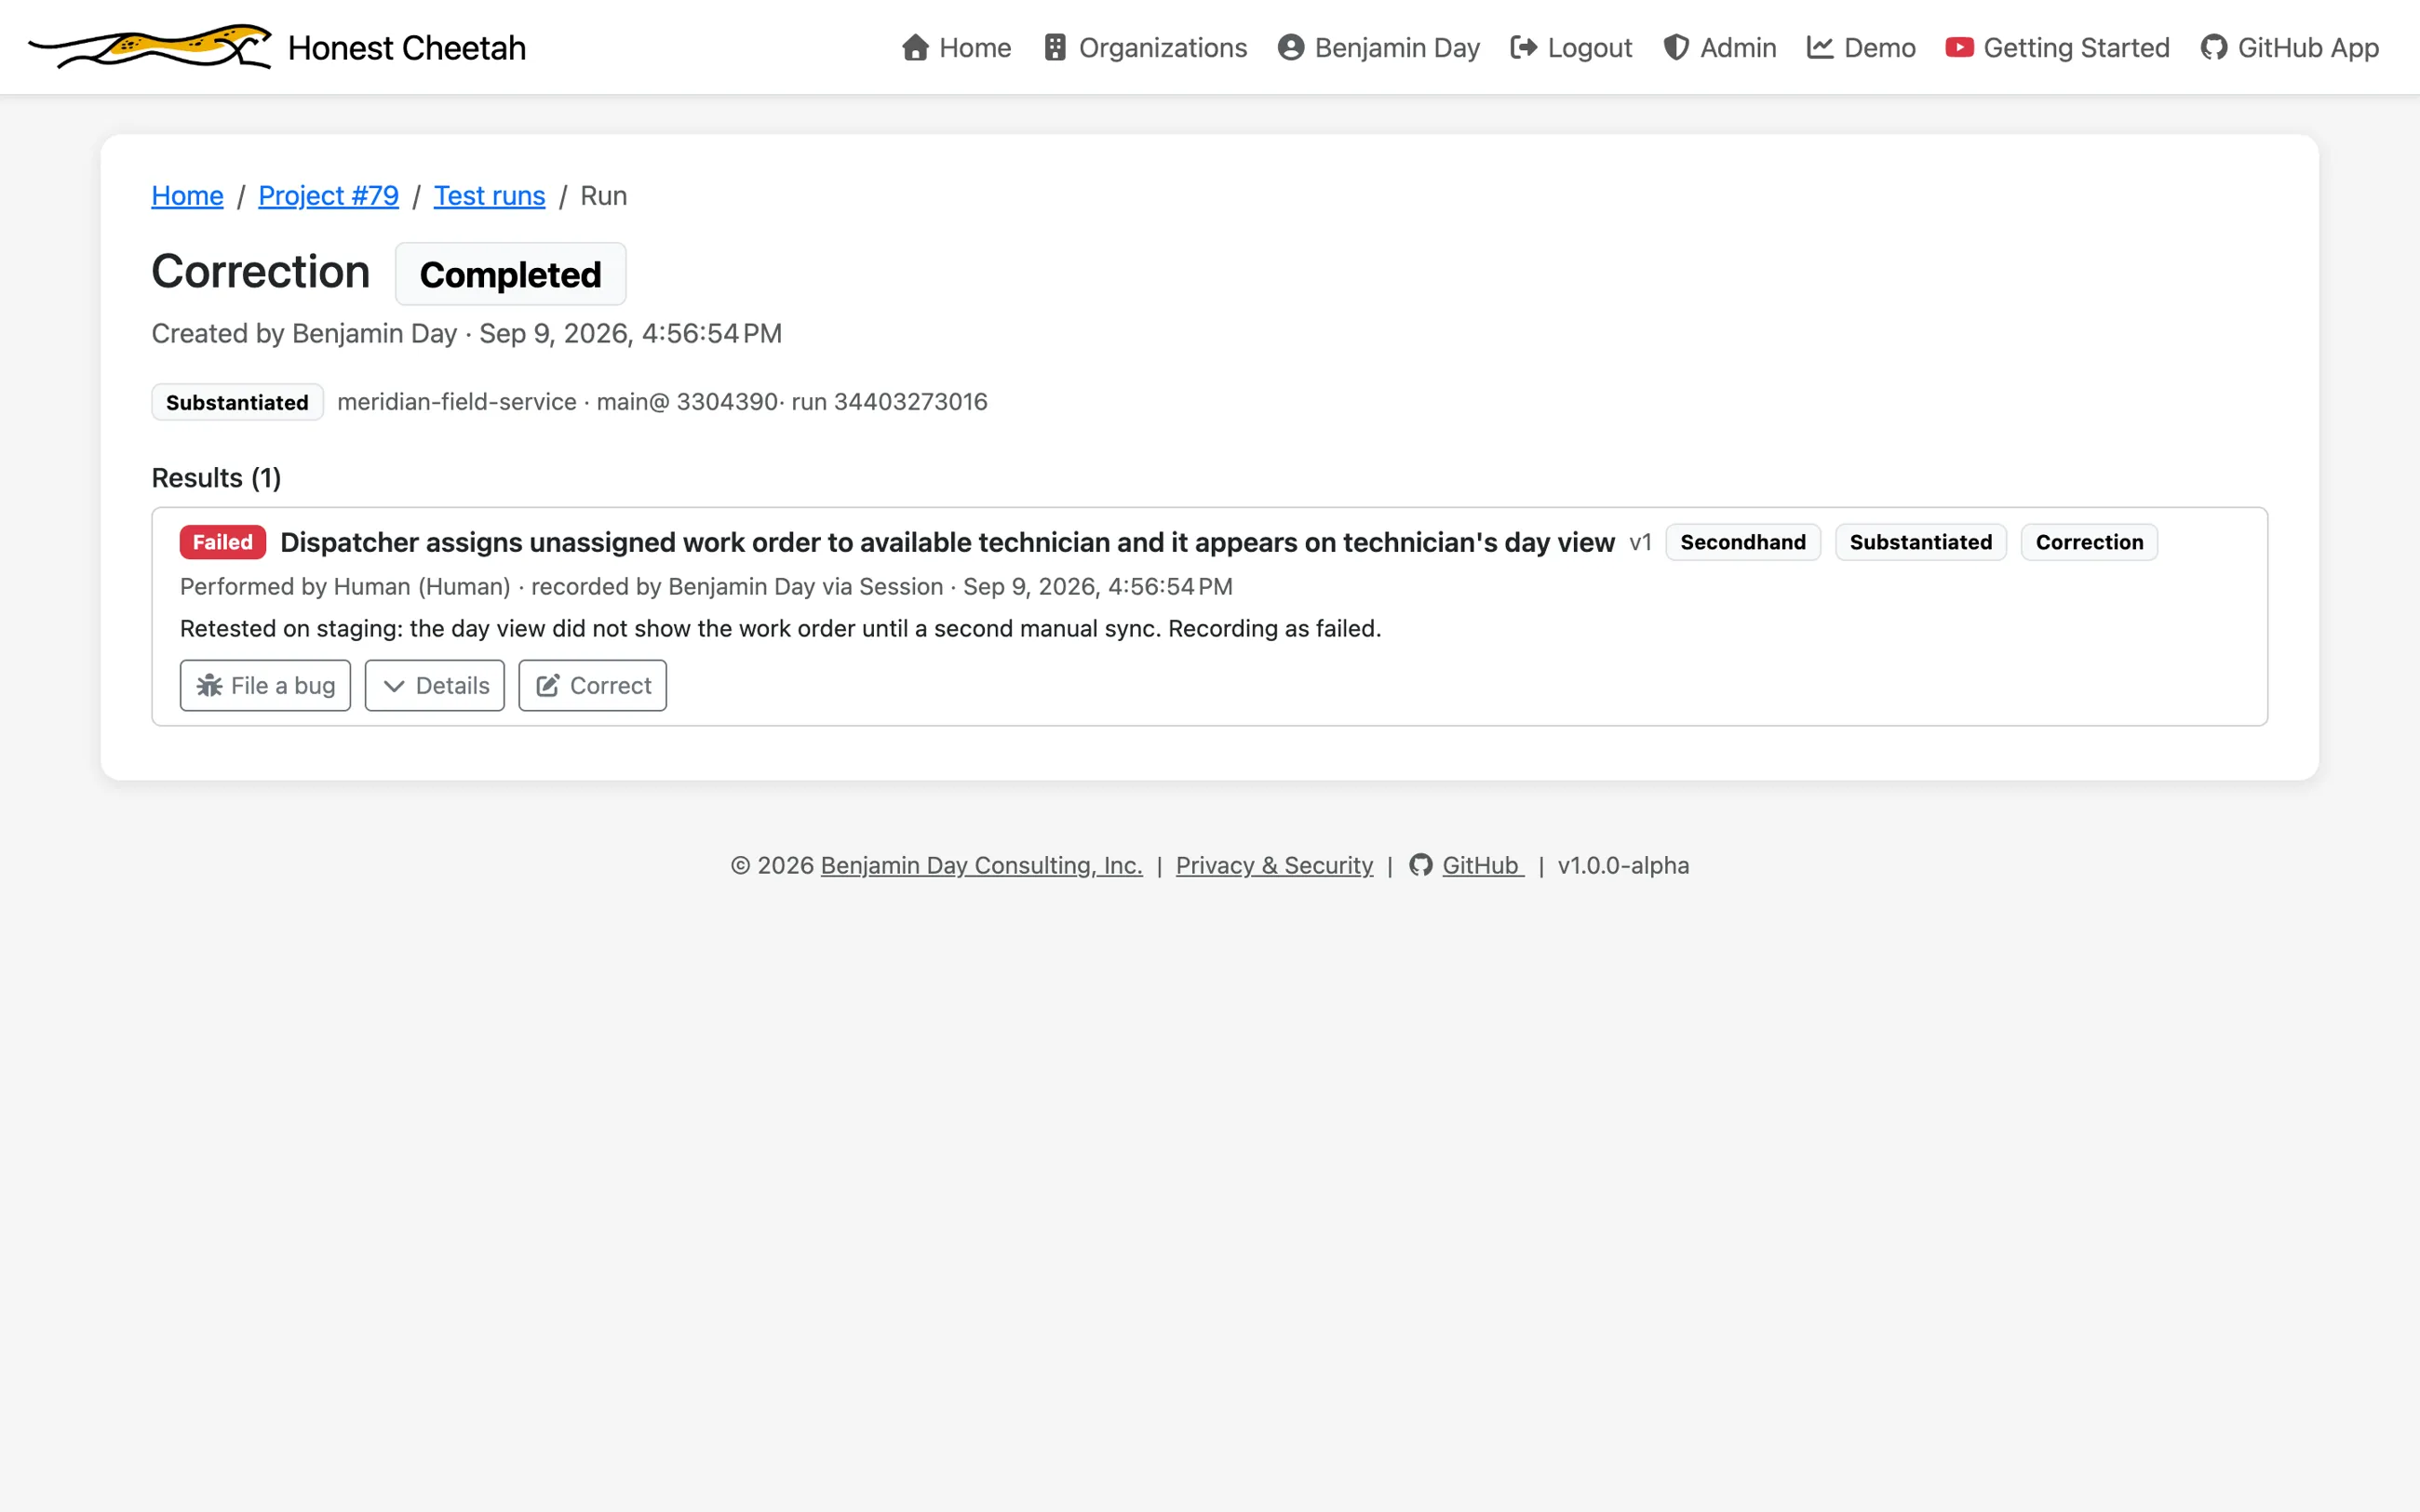
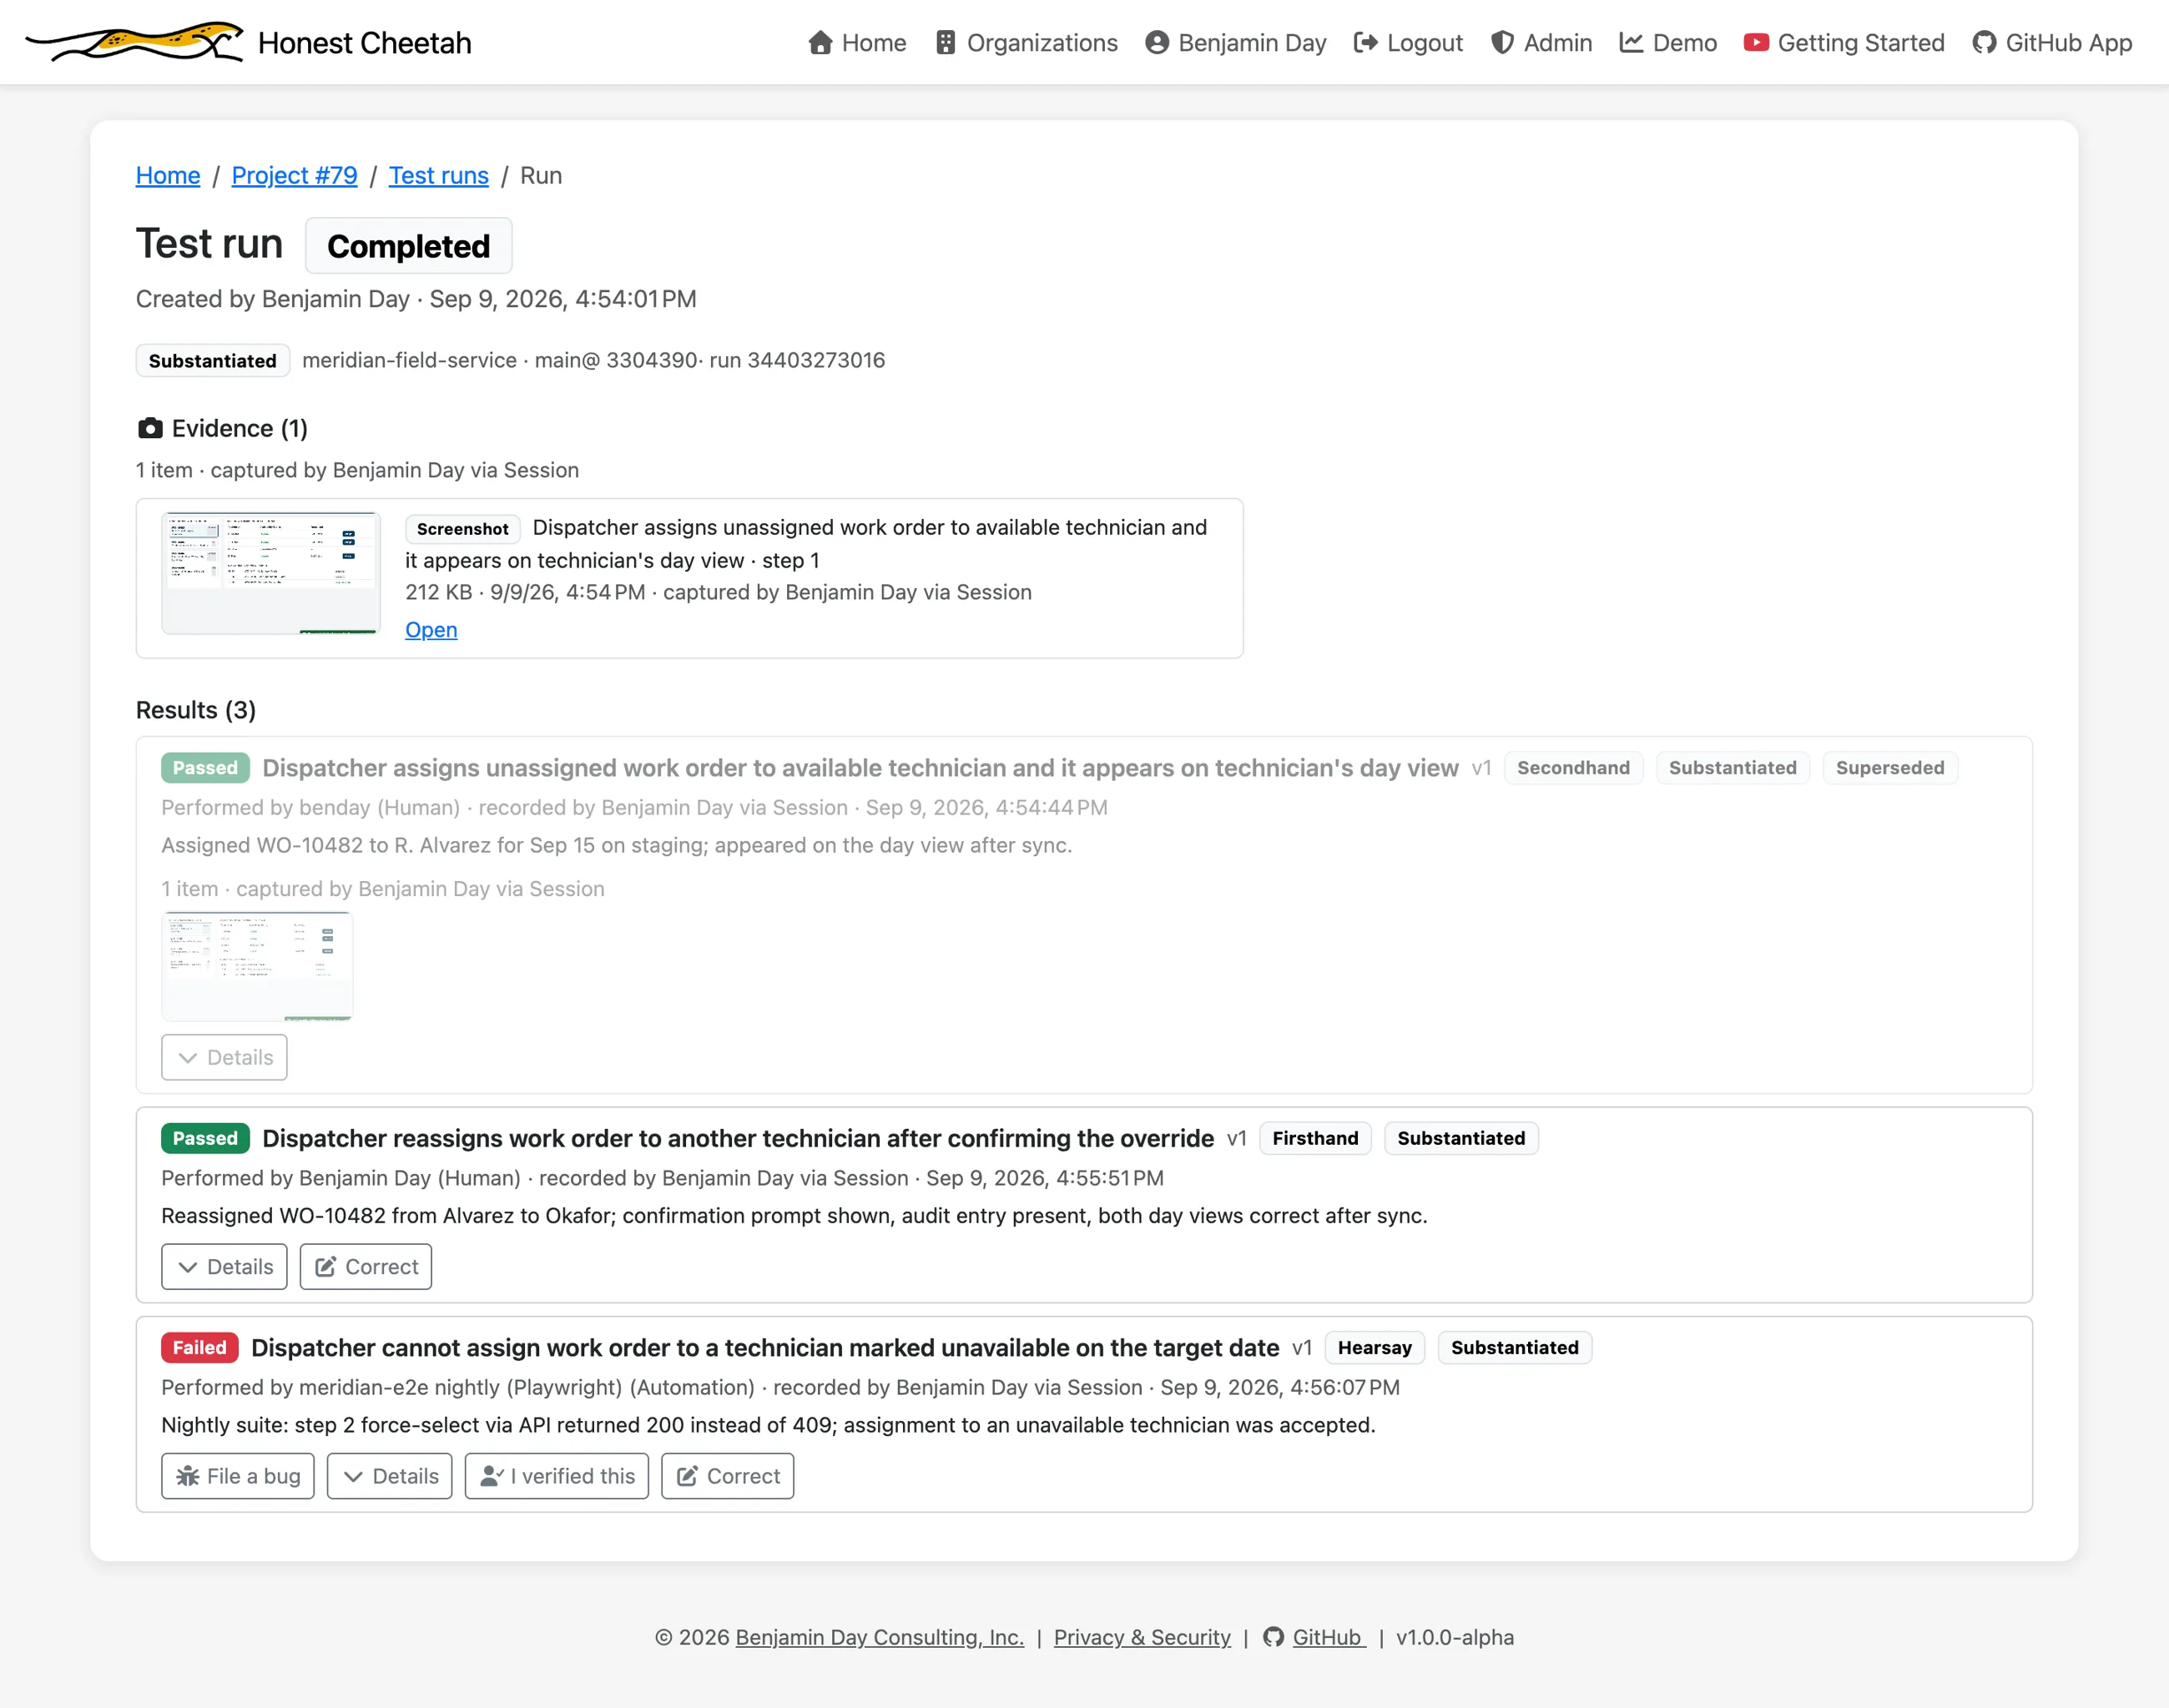
The labels are derived, not declared. From the stored facts, every result gets two plain-language labels at read time. Nobody picks their own.
Who did the testing, and how do we know?
- Firsthand
- A human did it and recorded it themselves, in their own session.
- Secondhand
- A human did it, but someone else recorded it.
- Corroborated
- An agent or automation did it, and a named human reviewed the result.
- Hearsay
- An agent or automation did it, and nobody has reviewed it.
- Unattributed
- No one is recorded as having performed it.
What build is this result about?
- Substantiated
- Bound to a specific GitHub Actions workflow run.
- Preliminary
- Bound to a pull request.
- Declared
- The tester typed what they tested against: an environment or an address.
- Unsubstantiated
- Not attached to anything.
Firsthand, Secondhand and Corroborated count as human-verified. Hearsay and Unattributed don't. That's the product's whole position on AI-run tests, and it's enforced in the schema, not in a setting.
"Hearsay" is not an insult. Most of your verification is going to be hearsay, and that's fine; nobody can personally re-run every test on every build. The point is to know which green checkmarks are which, so that at the release, the audit or the incident review you can tell "verified" from "vibes." None of the labels is red. The words carry the judgment. And every Hearsay result has an I verified this button: click it, and a named reviewer is recorded and the label becomes Corroborated.
If you're the person who has to sign your name to a release, for a customer, a regulator, an insurer or a board, this is the part built for you.